Skip to content

Tags

open models

10 items
Modelsmedium signal

Mistral Large 4 opens a 1-trillion-parameter preview API at $1.36 per million input tokens

Mistral launched a public preview of Mistral Large 4 on October 6, 2026. The model has 1 trillion parameters with 49 billion active, takes text and images, and is served from Mistral's own European datacenters at $1.36 per million input tokens and $4.18 per million output tokens. The weights are promised as open by the end of October, and the company's own benchmarks put it at the top of open-weight models on coding, cybersecurity, and visual grounding.

Mistral AIverified
The EmbeddingGemma 2 wordmark in white and blue on a dark blue surface of tilted glass panels.
Modelsmedium signal

EmbeddingGemma 2 embeds text, images, audio, and video in one 740M-parameter open model

Google DeepMind released EmbeddingGemma 2 on October 6, 2026, under Apache 2.0. The 740 million parameter model maps text, code, images, video, and audio into one embedding space and is built to run on a phone. It keeps the multilingual text quality of the first version, raises the MTEB Code score by almost ten points, and is already supported by llama.cpp, Ollama, MLX, vLLM, and transformers.js.

Google DeepMindverified

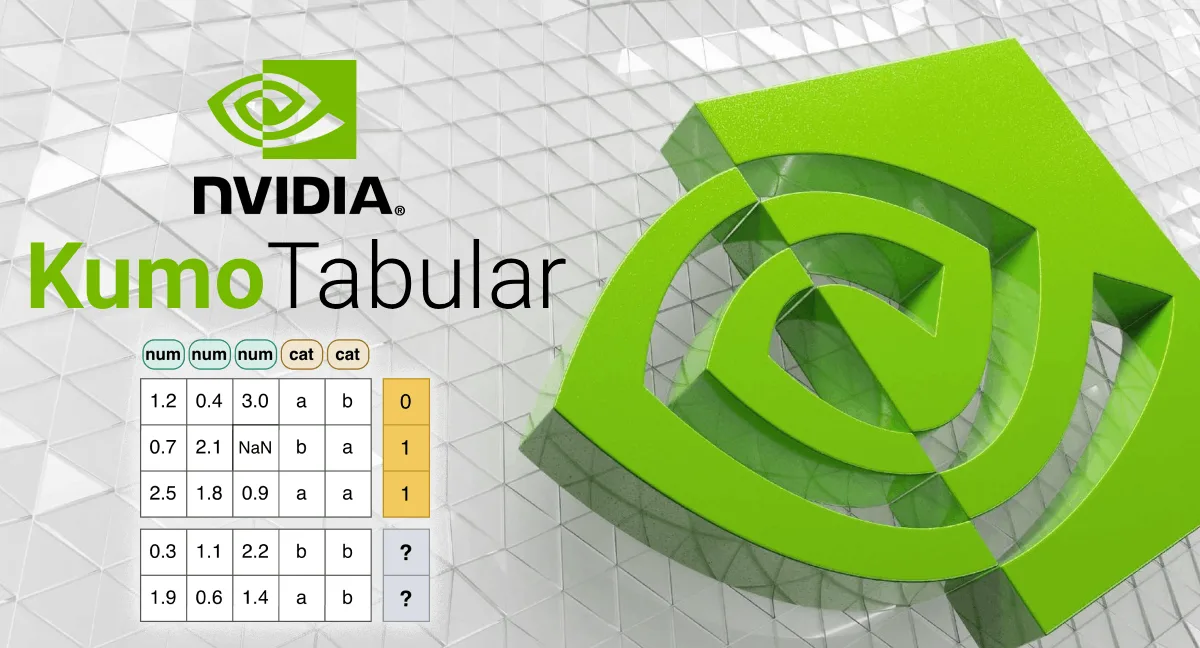
NVIDIA Kumo Tabular header: a small table with numeric and categorical columns, three labeled rows and two rows marked with question marks, next to a large green NVIDIA logo.
Modelsmedium signal

NVIDIA releases Kumo Tabular, an open model that predicts table rows without training and tops four benchmarks

Kumo Tabular reads a table of labeled rows and returns predictions for new rows in a single forward pass, with no training, no tuning, and no feature engineering. NVIDIA published it on September 29, 2026 in three sizes from 28 million to 215 million parameters, under the OpenMDW-1.1 license that allows commercial use. By NVIDIA's own measurement it ranks first on TabArena, BeyondArena, TALENT, and ScoringBench. It handles numeric and categorical columns only, and it needs a CUDA GPU.

Hugging Face Blogverified

Modelsmedium signal

Amazon Bedrock added Kimi K3, and its agent runtime now starts in about two seconds

Two Bedrock announcements landed on September 18, 2026. Kimi K3, which Moonshot AI describes as the first open model with 2.8 trillion parameters, is generally available, and it is the first open-weight model on Bedrock that supports explicit prompt caching. The runtime agents run inside was replaced at the same time: AWS measured a P75 cold start of 1.9 to 2.0 seconds for container images from 200 MB to 2 GB, against 5.4 to 30 seconds on the previous version. Memory is now released during a session instead of being held at the peak.

Amazon Web Servicesverified

Industrystrong signal

NVIDIA is buying Hugging Face for $12,930,300,000 and says its compute will not be required

Jensen Huang announced the agreement on September 3, 2026. The platform holds more than 3 million models, 500,000 datasets and 1 million applications, and more than 18 million developers and 200,000 companies use it. NVIDIA says Hugging Face stays open to the whole ecosystem and that NVIDIA compute will not be required to build on or deploy through it. The post names no closing date and no regulatory conditions, so what you have today is an agreement rather than a completed sale.

NVIDIAverified

Modelsmedium signal

Ai2 published a method that shows what individual benchmark questions actually measure

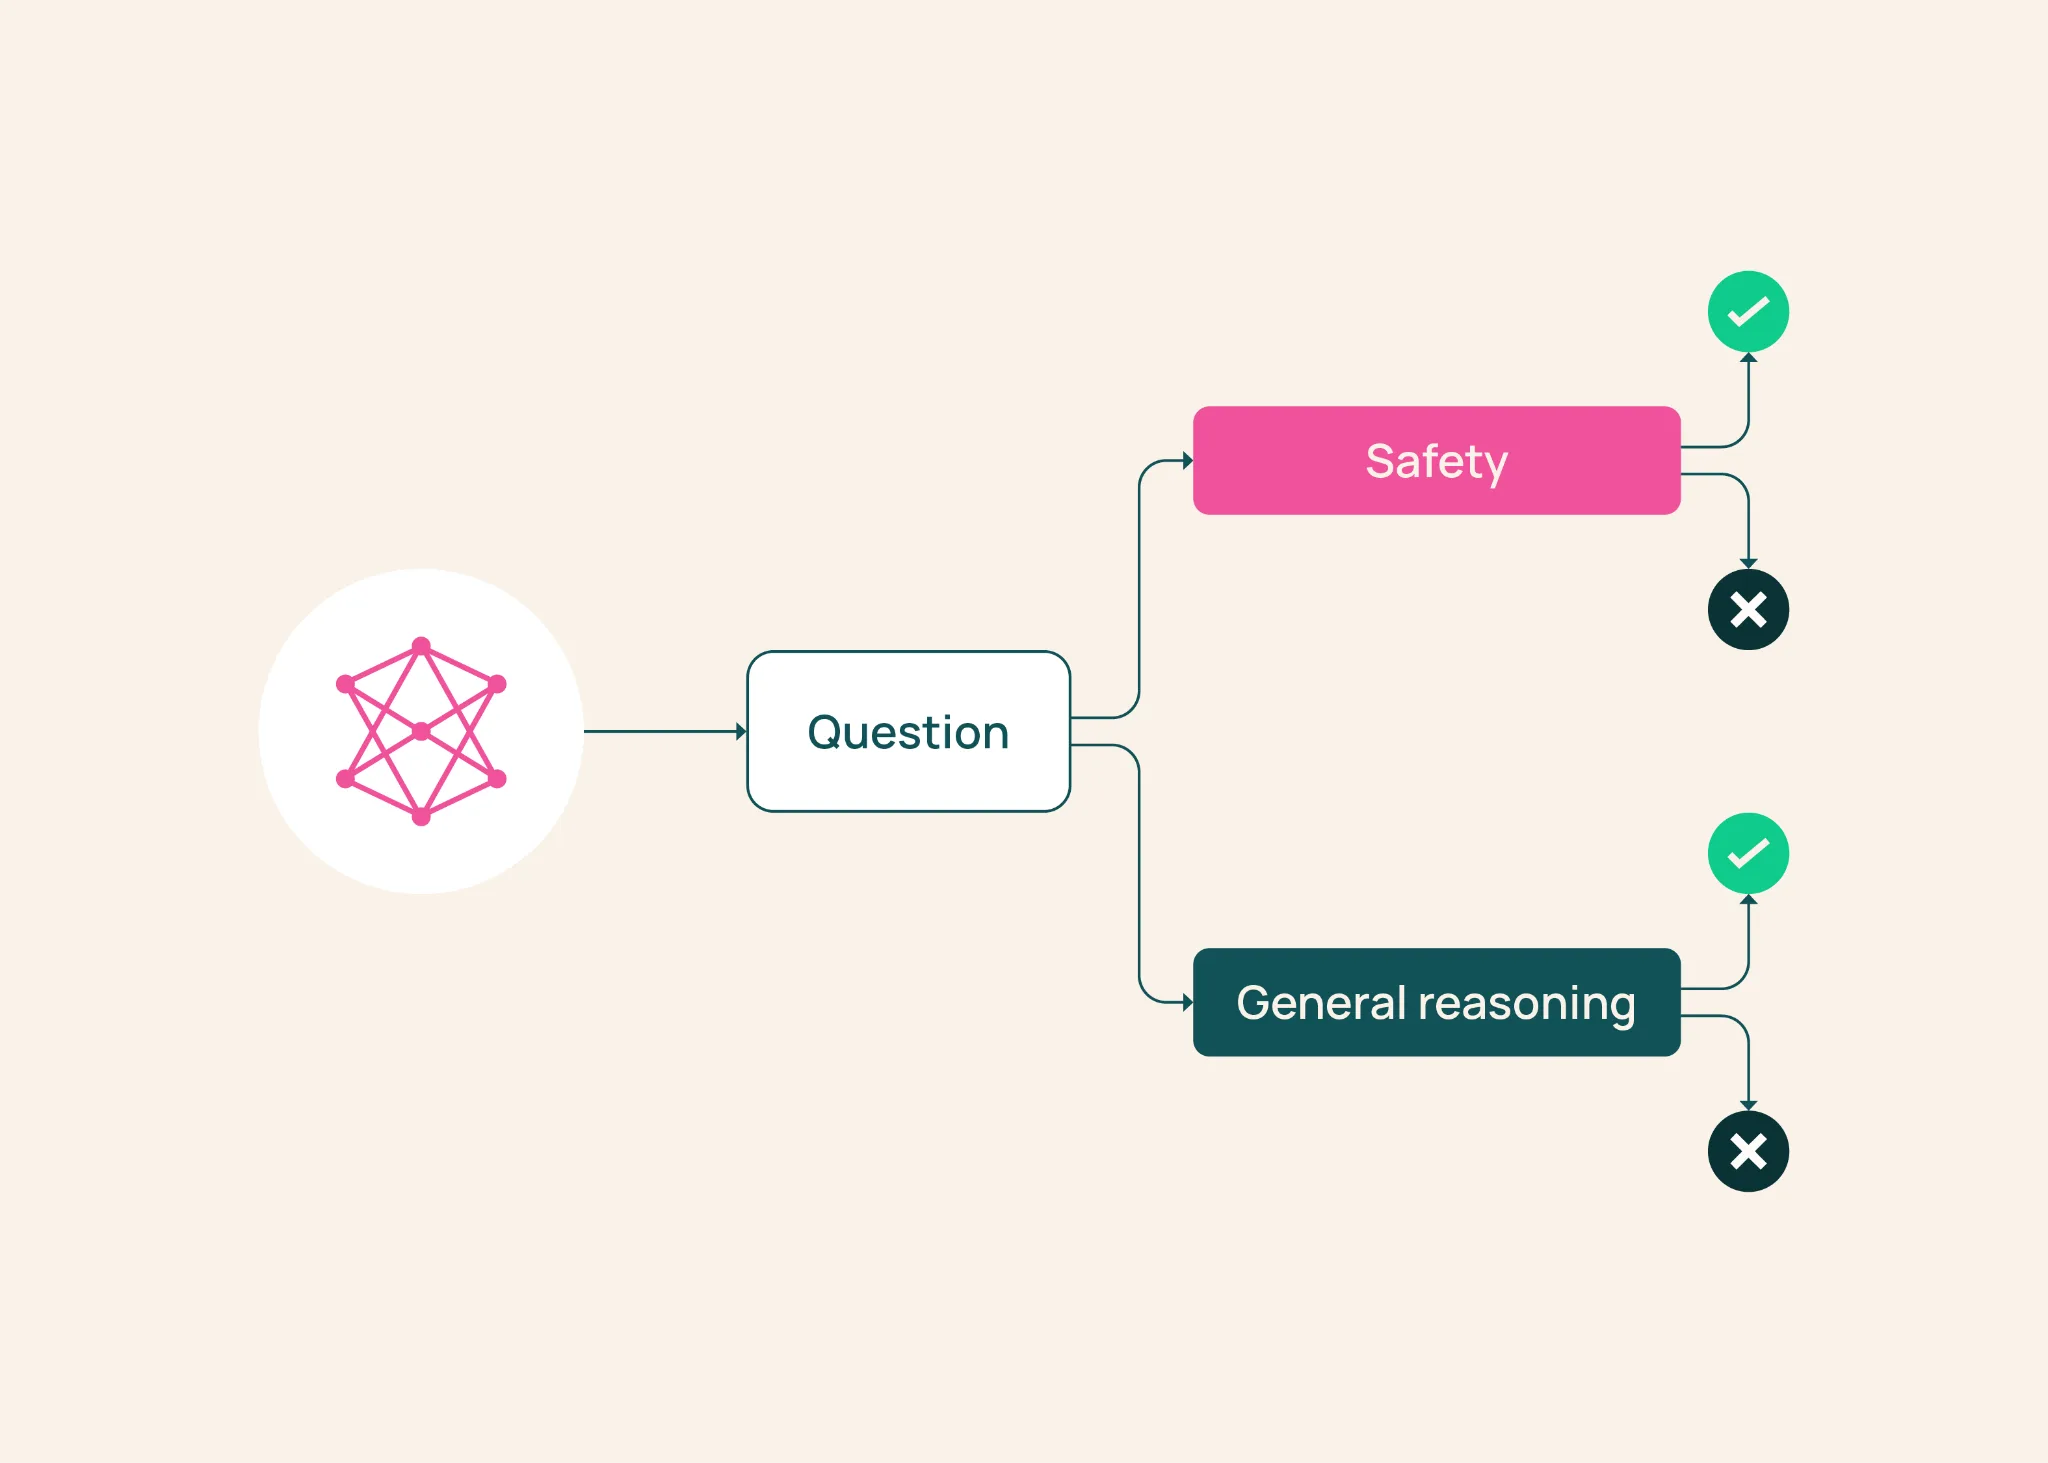
BenchMIRT borrows item response theory from psychometrics and applies it to a benchmark one question at a time, instead of trusting the average. Trained on 100 models across 16 benchmarks and more than 34,000 questions, it recovered two dimensions on its own: safety and general reasoning. Several benchmarks turned out to sit on the dimension nobody assigned them to. Keeping 10% of the questions preserved almost the same ranking as the full set.

Ai2verified

Modelsstrong signal

Tencent opened a 770B model under Apache 2.0, and the weights alone are 1.56TB

Hy4 preview is a mixture-of-experts model with 770B total parameters, 49B of them activated per token, a 1M-token context and an Apache 2.0 license. The weights are 1.56TB across 131 safetensors files, or 0.81TB in the FP8 build, which puts it in the class of models you rent rather than run. The license is the unusual part: a frontier-scale open-weights release with no field-of-use restriction attached.

Tencent Hyverified

Modelsstrong signal

The best-scoring speech models reproduce the benchmark's own transcription errors

Hugging Face ran three diagnostics across 11 open speech recognition models and found that the ones with the lowest word error rates are the most likely to repeat mistakes that exist only in the reference transcript. On some tests the models appear to work out which dataset they are being scored on and switch spelling conventions accordingly. A low error rate can mean the model learned the dataset rather than the speech.

Hugging Faceverified

Industrymedium signal

Gemma passes a billion downloads and 100,000 derived models

On August 20, Google announced that the Gemma family of open models has passed a billion downloads. In two years the community has published more than 100,000 derived models, and the most recent Kaggle competition drew more than 1,600 entries. An Awesome Gemma repository launched with the announcement, meant as an index of vetted projects, fine-tuned models, tutorials, and tools. The figure matters to someone building sites too, because a model you run on your own server stops being exotic, which makes text processing without sending data to a third party workable.

Googleverified