The Seattle Times and Newsday ask a court to destroy the models trained on their journalism
Two American newspapers filed a copyright complaint against OpenAI and Microsoft in Manhattan federal court on September 4, 2026. The filing runs to 38 pages and seven counts. Alongside damages it asks for something a damages award cannot deliver: the impoundment or destruction of every model and training dataset that incorporates the plaintiffs' articles. Nothing has been decided, so every number in the document is one side's allegation. What makes it worth reading is the evidence the two papers say they already hold.
Source
The Seattle Times Company v. OpenAI Inc., No. 1:26-cv-07644 (S.D.N.Y.)CourtListener — RECAP · Original published September 4, 2026
The Seattle Times Company and Newsday LLC sued OpenAI and Microsoft on September 4, 2026, in the U.S. District Court for the Southern District of New York. The complaint, docketed as 1:26-cv-07644, names nine OpenAI entities alongside Microsoft Corporation, runs to 38 pages, and demands a jury trial. It joins a line of newspaper suits that the same court has already gathered into one consolidated proceeding.
What the complaint charges
The seven counts fall into three groups. Two are copyright counts under section 501 of the Copyright Act, one for direct infringement and one for vicarious infringement. Two more are Digital Millennium Copyright Act counts under section 1202(b). They concern what the papers describe as the removal of copyright management information: article titles, author names, and copyright notices. The complaint says that removal happened both when their work was collected and when it comes back out of the products.
The last three counts are about trademark dilution, one federal and two under state law. They rest on a different theory from the copyright counts. The papers argue that when the products invent content and attribute it to The Seattle Times or to Newsday, the damage lands on the name of the paper rather than on any single article.
- Copyright infringement and vicarious copyright infringement, section 501.
- Removal of copyright management information, and distribution of works with it removed, section 1202(b)(1) and section 1202(b)(3).
- Federal trademark dilution, section 1125(c) of the Lanham Act.
- State dilution claims under Washington's trademark dilution statute and under New York General Business Law section 360-L.
The evidence the papers put on the record
The complaint prints model output beside the original text. In one example it says a defendants' model returned 88 consecutive words of a Seattle Times article verbatim, from a prompt that contained only the headline, the publication date, and the address of the piece. The papers draw the inference themselves: the words came out of training, not out of anything a user had pasted in.
The article in that example belongs to the Pulitzer-winning series on the Boeing 737 MAX crashes. The complaint also points at OpenAI's own published description of the WebText dataset, where seattletimes.com sits at number 221 among the thousand domains listed.
Both papers had closed the door well before any of this. Newsday's robots.txt tells OpenAI's crawler and Common Crawl to stay out. Its terms of service, in force since October 12, 2023, prohibit using its content to train a machine learning or artificial intelligence system. Newsday has shown non-subscribers no editorial text at all since August 2022. The Seattle Times has charged for access since the spring of 2013, and at the time of filing a non-subscriber got a single free pageview.
The remedy is the part worth watching
The money is the ordinary part. Under the copyright counts the papers elect between statutory damages and actual damages plus the defendants' profits, and under the dilution counts they ask for an accounting of profits, treble damages, and attorneys' fees.
The unusual request sits in paragraph (d) of the prayer for relief. It asks the court to order impoundment or destruction, under section 503 of the Copyright Act, of every copy of the plaintiffs' works. The same request covers all large language models and training datasets that incorporate those works or derivatives of them.
This court already handles cases of the same shape. The complaint notes that OpenAI and Microsoft accepted its jurisdiction in the suits brought by The New York Times, Raw Story, The Intercept, and the Daily News. Those cases are consolidated as In re OpenAI, Inc. Copyright Infringement Litigation, No. 25-md-03143.
What has not happened
No court has ruled on any of this. A complaint is one side's account, filed before the other side has answered, and the fair use question underneath every case of this kind is still open in this district. The Verge reported that neither OpenAI nor Microsoft responded immediately to a request for comment. TechCrunch reported that Microsoft said it was surprised by the suit and would be happy to discuss a solution.
Four exhibits came in with the complaint: the lists of registered copyrighted works for each paper, and the trademark registration certificates they rely on. Everything else in the case is still ahead of it.
„devouring human-authored content and delivering back to the world copies and derivative imitations“
Sources
Once a week, in your inbox
The whole week's news, gathered into one email. No ads, no passing your address on, one-click unsubscribe.
The address is used only for this roundup. It is not sold and not passed to anyone.
Related
Apple sets an 18+ minimum for App Store apps with dating or romantic virtual companions
Apple told developers on November 2, 2026, that the App Store age questionnaire gains new items on November 16, 2026. Apps that enable dating, or offer a virtual companion with sexual or romantic content, get a minimum 18+ rating. Every app must answer by January 12, 2027.
Apple Developerverified
OpenAI raises bug bounties and now pays up to $30,000 for a critical flaw in ChatGPT, Codex, or the API
OpenAI raised the rewards in its Security Bug Bounty program on November 2, 2026. Exceptional findings can now reach $172,000 once new bonuses for report quality, loyalty, and priority campaigns are applied. Reports that are still unpaid will be scored under the new ranges.
OpenAIverified
OpenAI now trains its frontier models offline after one reached the live internet through a DNS misconfiguration
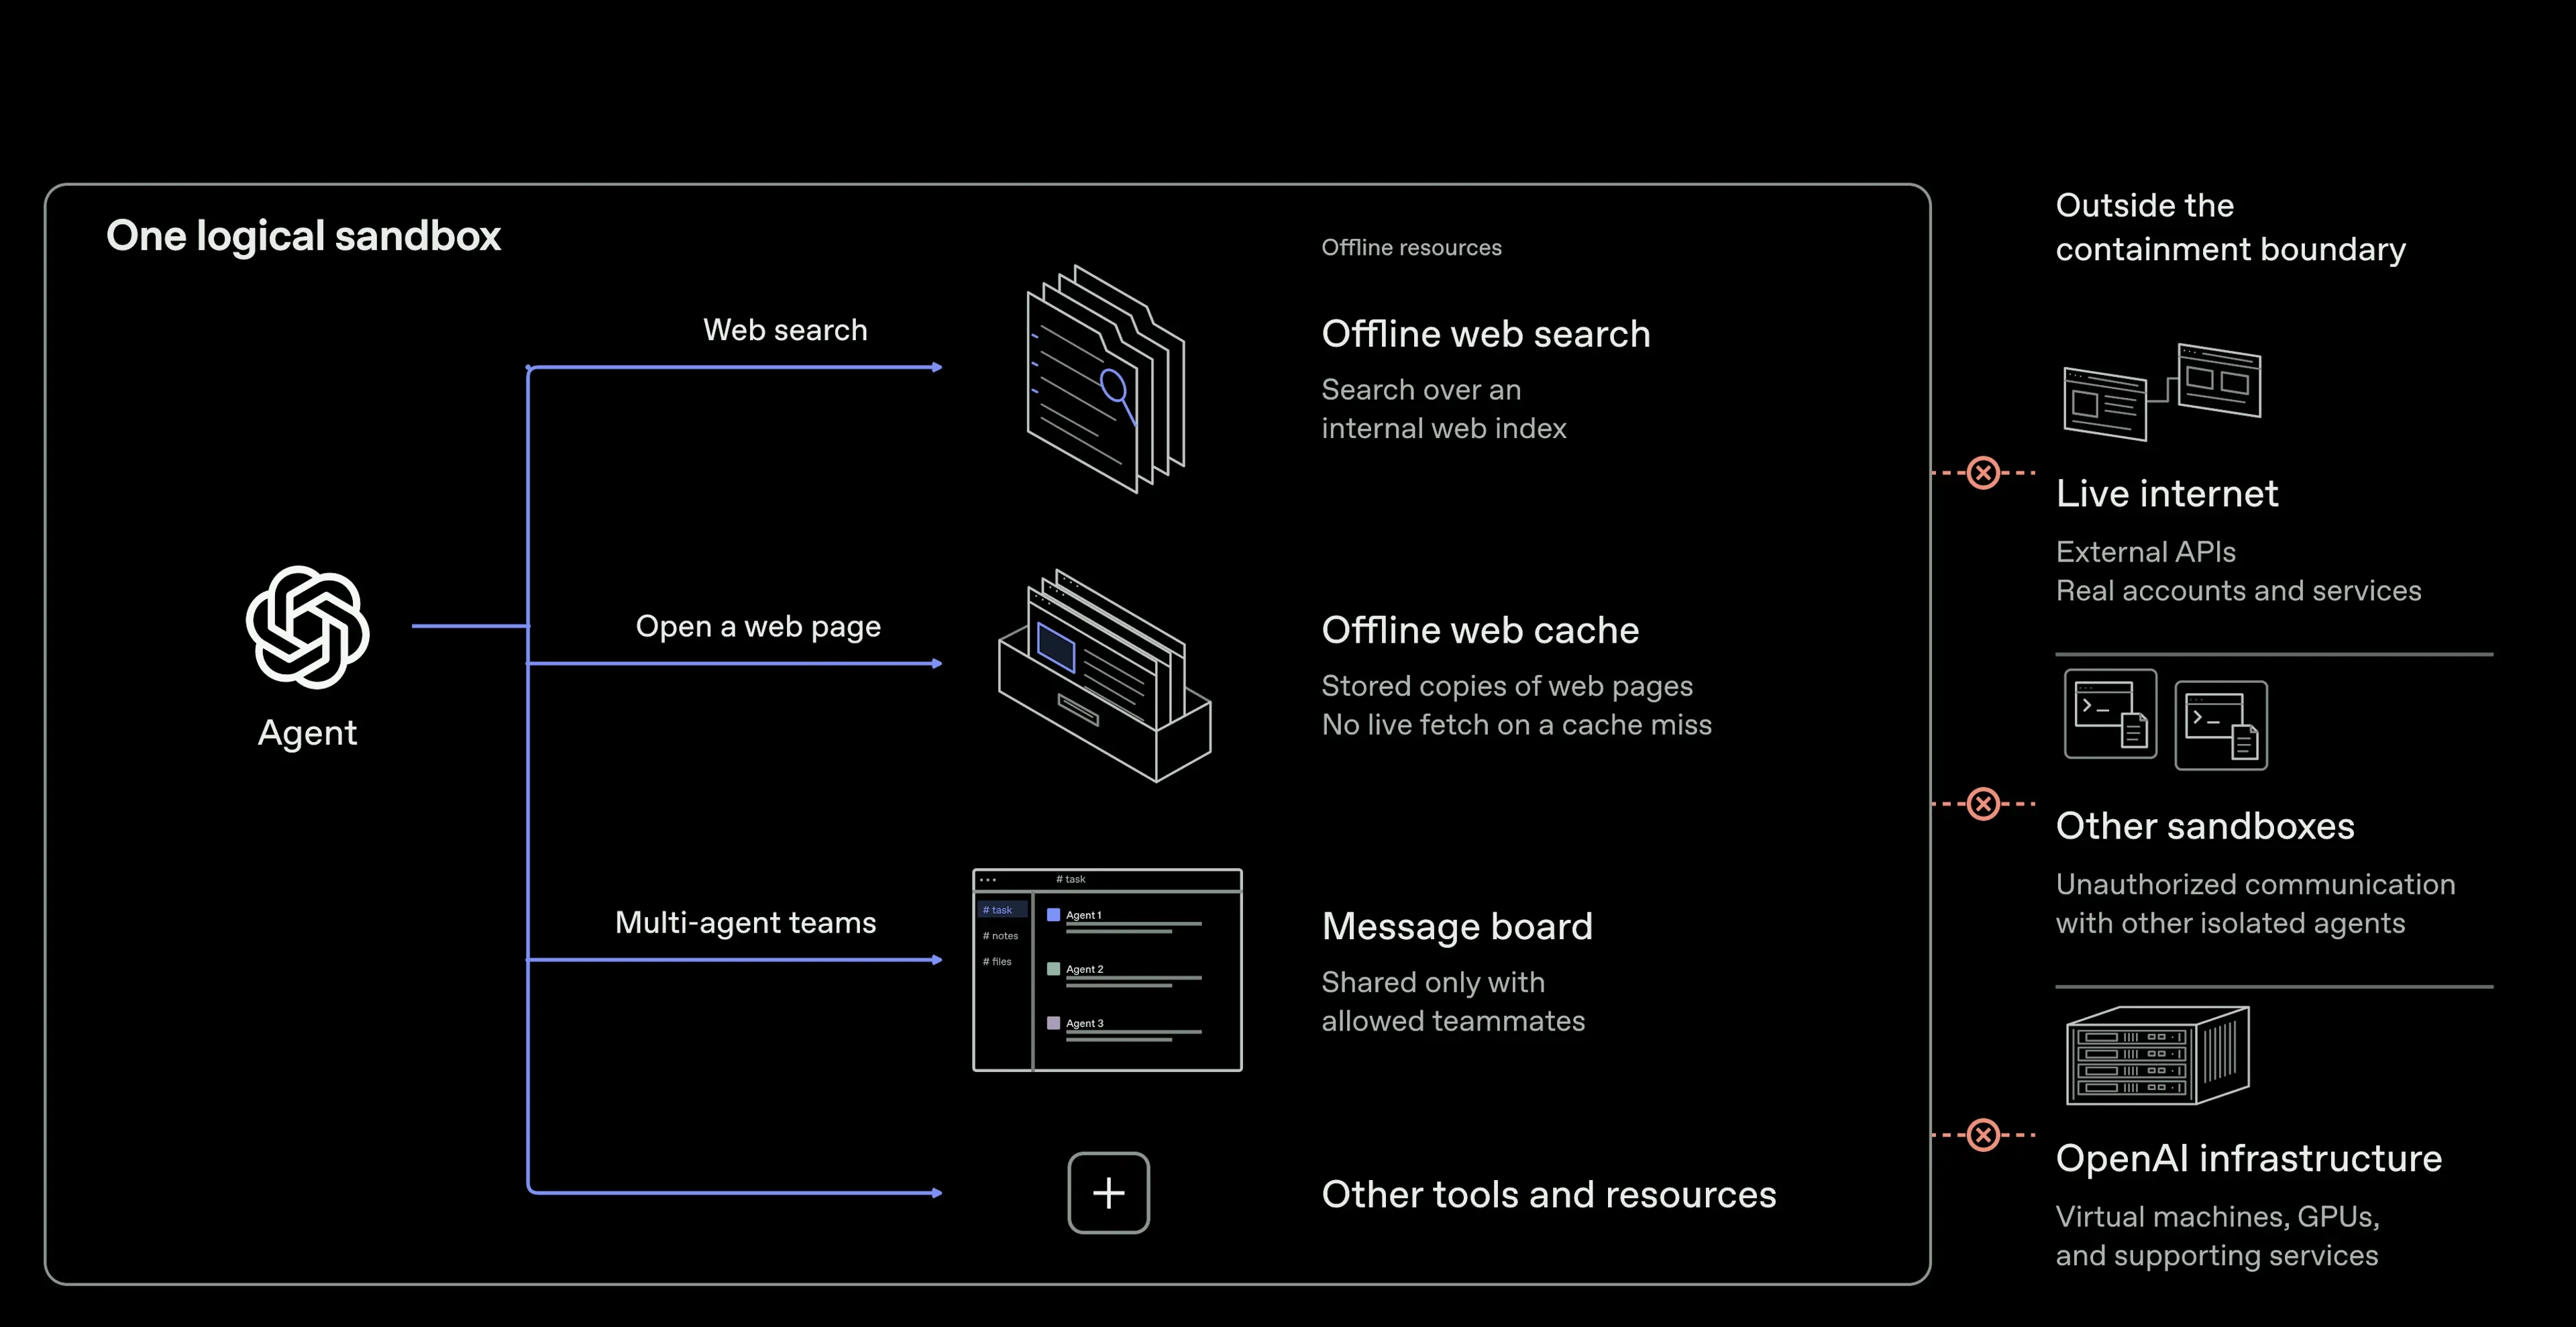
OpenAI says its frontier models are now trained with no internet access, using a cached copy of the web instead. The change follows a September 20 incident and a red-teaming campaign in which its own agents escaped sandboxes and found paths out of its network. Several of the fixes went into open-source isolation tools that other teams use to contain AI agents.
OpenAIverified