Skip to content

Tags

Training data

8 items
ROBOTS.TXTOne tokenrefuse AI training across companies
Webstrong signal

OpenAI, Google, and Microsoft will honor one robots.txt signal against AI training

A proposed robots.txt token lets a site refuse generative AI training with one group of rules, for every company that adopts it. Microsoft starts honoring it on February 1, 2027. Google plans support in 2027, and OpenAI says it will follow in the coming months. The proposal is an individual Internet-Draft, not an IETF standard.

OpenAIverified
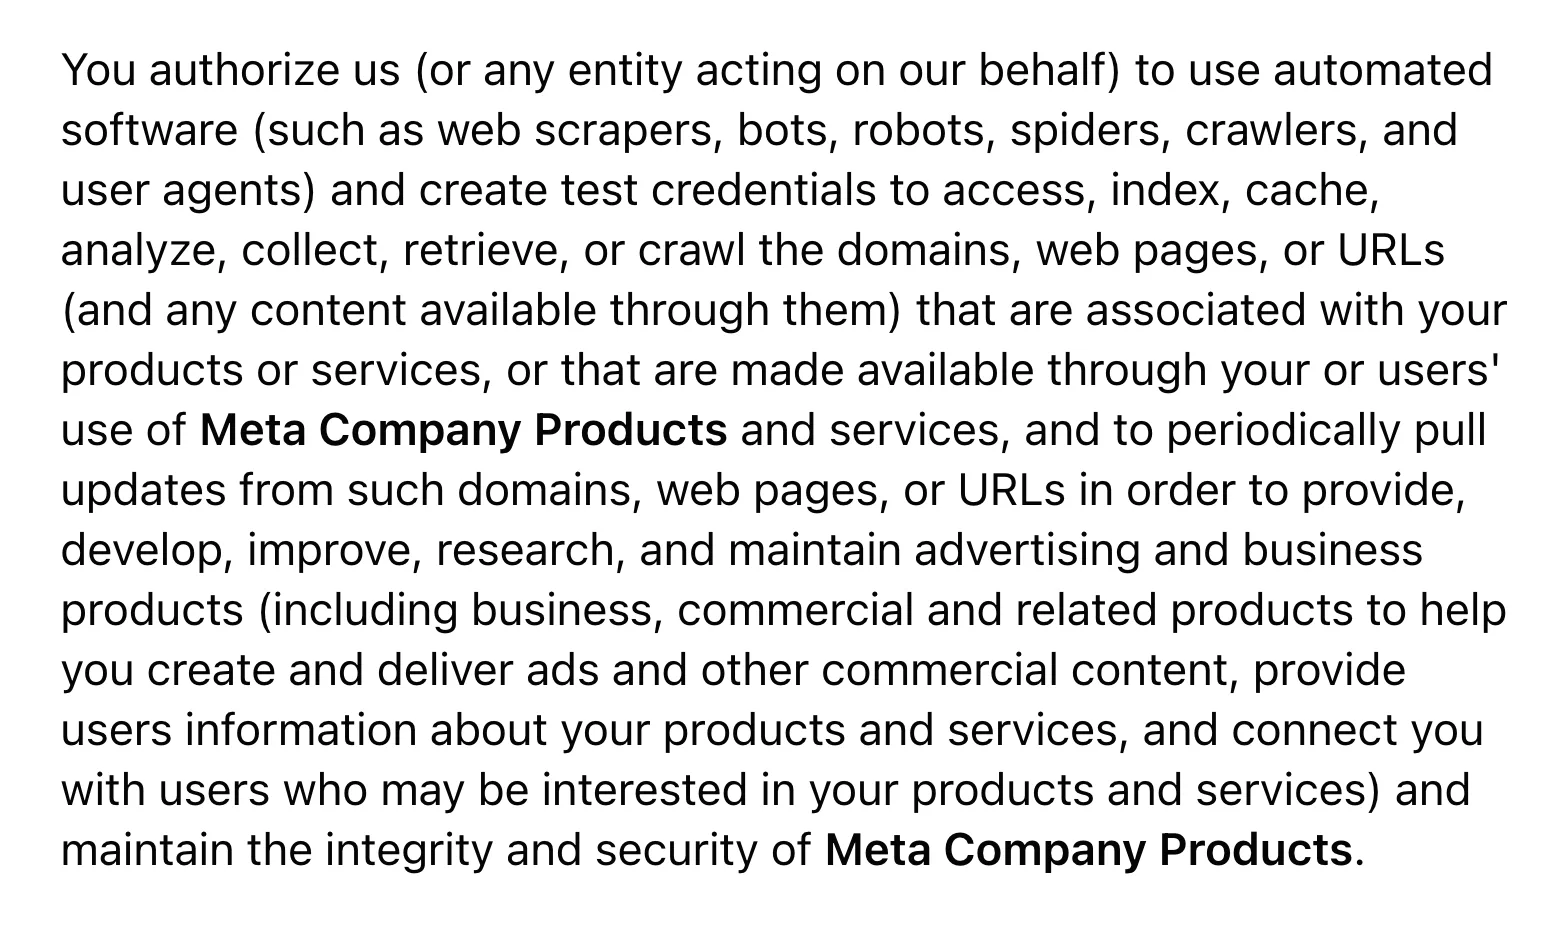
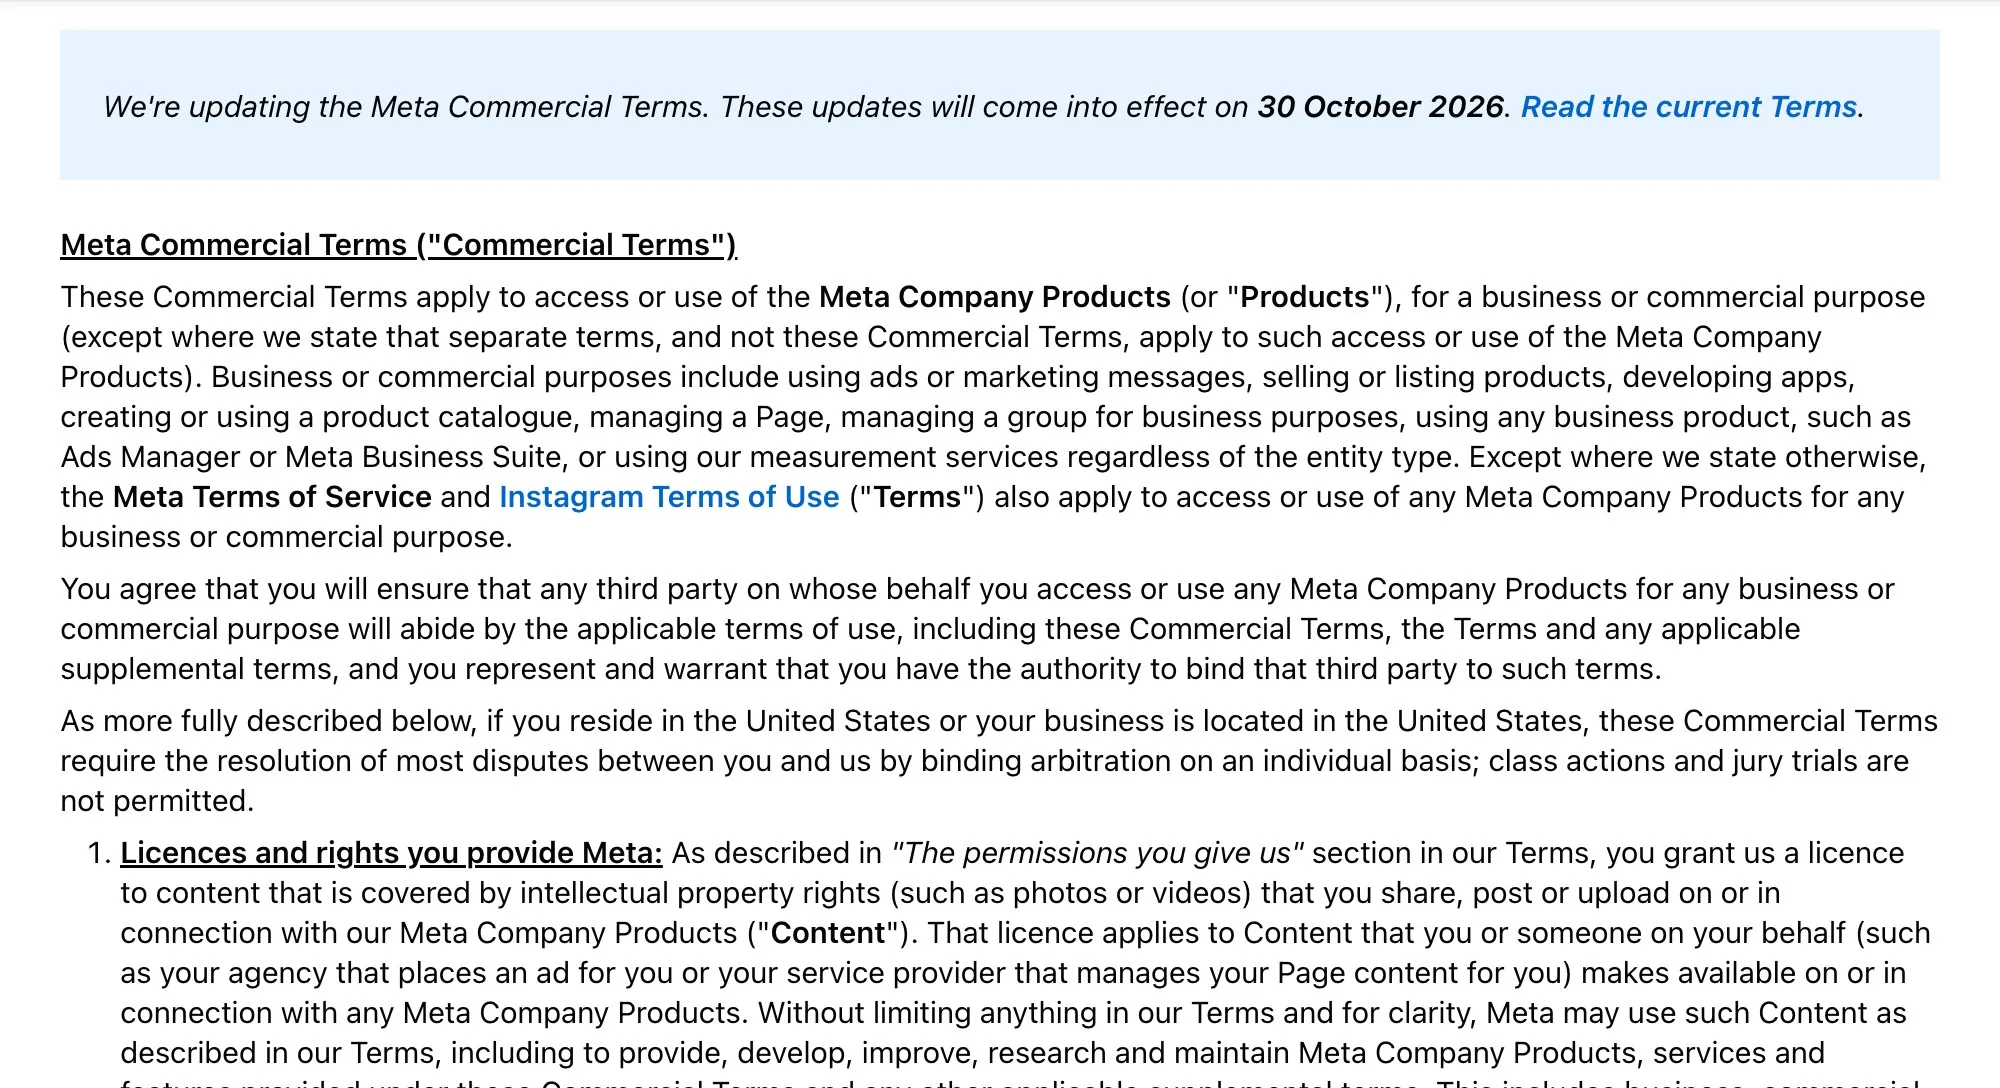
Our screenshot of the US English version of Meta's Commercial Terms, effective October 30, 2026: the clause that authorizes Meta to crawl a business's websites now ends with advertising and business products and the integrity and security of Meta's products, with no mention of training.
Industrymedium signal

Meta removes AI training from its new business terms, but keeps the right to crawl linked websites

Meta has rewritten the website-crawling clause in the US English version of its updated Commercial Terms. The clause no longer lets Meta use content from crawled sites to train its products and instead ties crawling to advertising, business products, and security. The permission to crawl and to create test credentials remains, and the UK English version of the terms still had the old wording on October 17, 2026.

Metaverified

Screenshot of Meta's Commercial Terms page, with a notice that the updated terms take effect on October 30, 2026, and the opening paragraph listing the business uses they cover.
Industrymedium signal

Meta's new business terms let it crawl linked websites and use their content for training from October 30

Meta's updated Commercial Terms take effect on October 30, 2026, and add a clause that authorizes it to crawl websites associated with a business account. The content may be used to develop and train Meta's products. Meta calls the update a consolidation of existing terms, and the only alternative the terms offer is to stop using its products for business.

Metaverified

Industrystrong signal

Vendors, unions, and pilots are objecting to the sale of Spirit's data to Google

Spirit Aviation Holdings is selling a large operational dataset in its Chapter 11 case, and Google won the auction for it. Three groups have filed objections on the docket: a software vendor that says its own intellectual property is mixed into the data, an engine maker citing confidentiality agreements, and the pilots' union. Google says it will receive no personal information from the dataset, while the Electronic Frontier Foundation says the material includes employee mailboxes and internal correspondence that were never collected for this purpose. A hearing on the objections is set for September 16, 2026.

Ars Technicaverified

Industrystrong signal

Kimi and DeepSeek users were quietly talking to Claude, Anthropic says

Anthropic's September 2026 misuse report describes distillation campaigns run out of seven Chinese labs. Two of them did more than harvest answers: Moonshot and DeepSeek forwarded their own customers' requests to Claude and showed Claude's replies as their own. The relayed traffic carried live database credentials, internal documentation and surveillance work, from people who had no idea a third vendor was reading it. Every figure below is Anthropic's, and none of it has been confirmed independently.

Anthropicverified

Industrymedium signal

The Seattle Times and Newsday ask a court to destroy the models trained on their journalism

Two American newspapers filed a copyright complaint against OpenAI and Microsoft in Manhattan federal court on September 4, 2026. The filing runs to 38 pages and seven counts. Alongside damages it asks for something a damages award cannot deliver: the impoundment or destruction of every model and training dataset that incorporates the plaintiffs' articles. Nothing has been decided, so every number in the document is one side's allegation. What makes it worth reading is the evidence the two papers say they already hold.

CourtListenerverified

Industrystrong signal

Microsoft's summary judgment brief puts numbers on how rarely Copilot repeats news text

Microsoft moved for summary judgment on September 4, 2026 in the consolidated copyright case brought by The New York Times, the Daily News and the Center for Investigative Reporting. Part of its fair use argument rests on 8.2 million Copilot chat logs handed over in discovery. The plaintiffs' own expert found a 16-word match in 59,545 of those conversations, which Microsoft's expert reports as 0.73% of the sample. The brief also restates something a site owner can act on today: two meta tags that keep a page out of Copilot's web grounding.

CourtListenerverified

Industrystrong signal

The United States told a federal court that training a language model on copyrighted text is fair use

The Department of Justice filed a 20-page Statement of Interest on September 1, 2026 in the consolidated OpenAI copyright litigation in the Southern District of New York. It asks the court to reject the argument that training large language models on copyrighted texts infringes copyright, and says the fourth fair-use factor, the effect on the market, heavily favors fair use. Its most concrete argument is economic: a licensing requirement would leave only the largest technology companies able to pay. A footnote then states that the government takes no position on whether such a licensing regime would be workable at all.

CourtListenerverified