Skip to content

Tags

search

8 items
The EmbeddingGemma 2 wordmark in white and blue on a dark blue surface of tilted glass panels.
Modelsmedium signal

EmbeddingGemma 2 embeds text, images, audio, and video in one 740M-parameter open model

Google DeepMind released EmbeddingGemma 2 on October 6, 2026, under Apache 2.0. The 740 million parameter model maps text, code, images, video, and audio into one embedding space and is built to run on a phone. It keeps the multilingual text quality of the first version, raises the MTEB Code score by almost ten points, and is already supported by llama.cpp, Ollama, MLX, vLLM, and transformers.js.

Google DeepMindverified
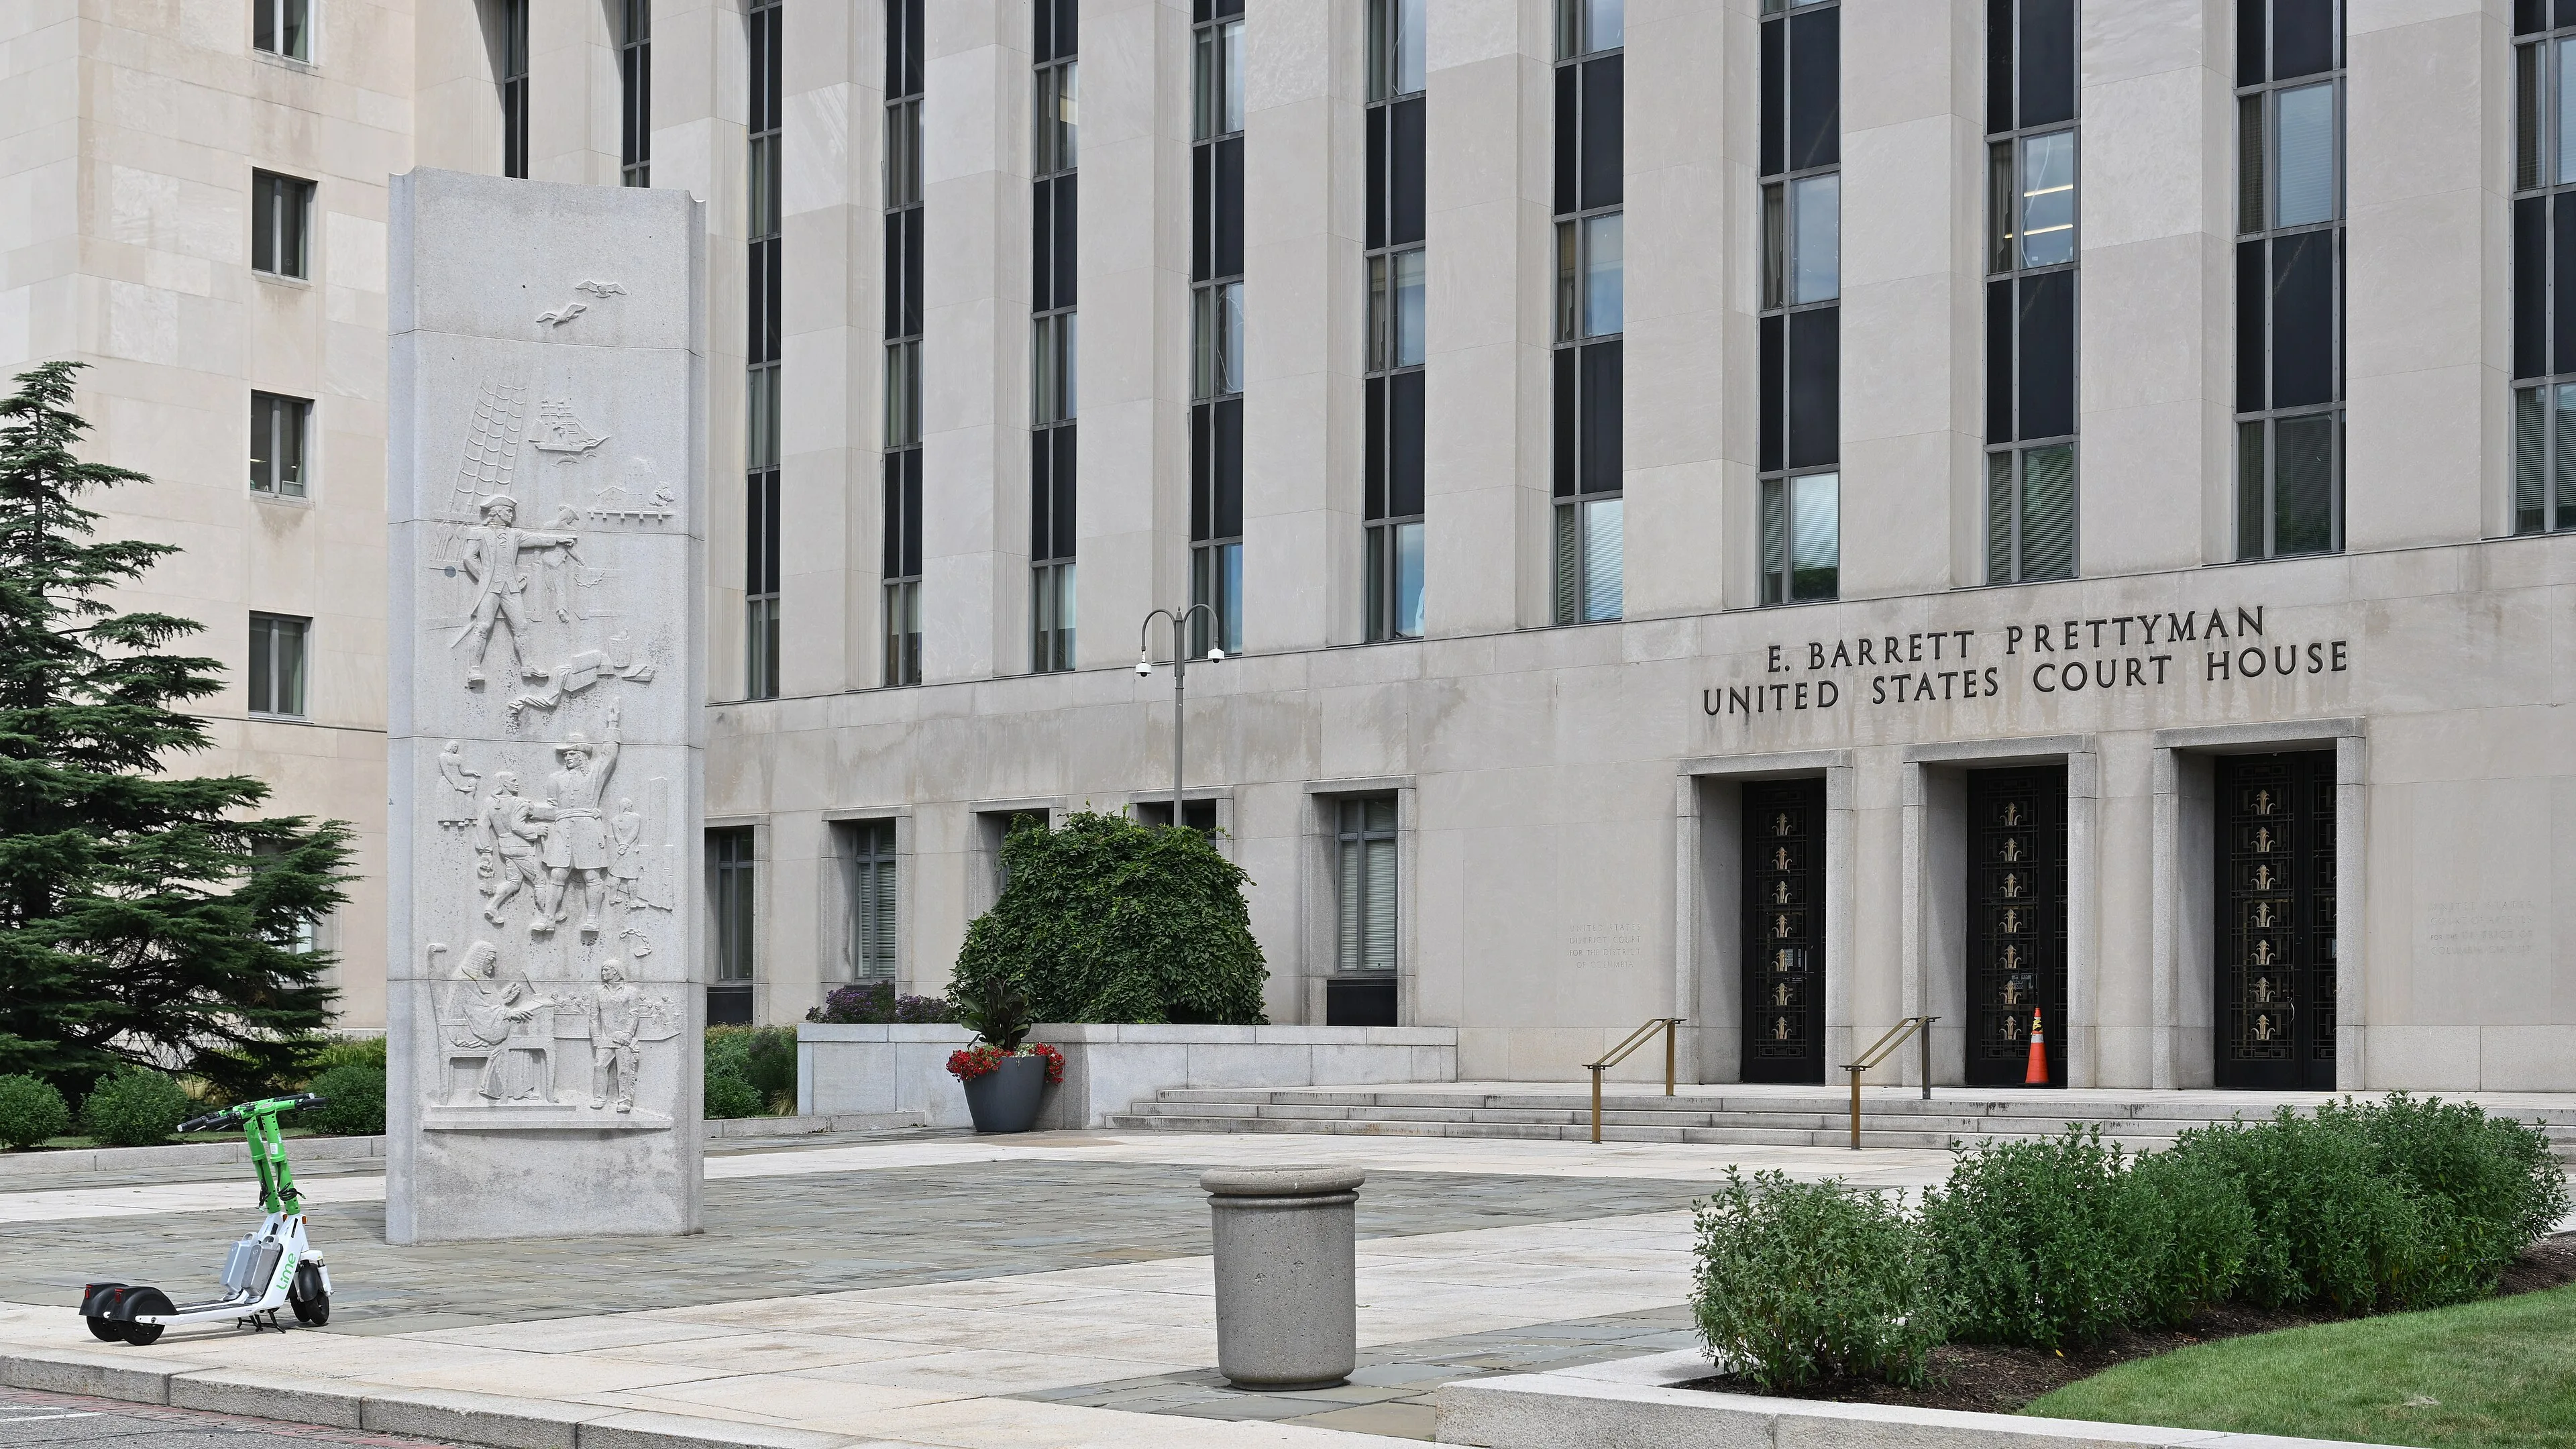
The front of the E. Barrett Prettyman United States Court House in Washington, the seat of the US District Court for the District of Columbia: a pale stone facade with the building's name above three dark doors, and a carved stone relief panel standing on the plaza.
Industrymedium signal

Federal judge dismisses Chegg and Penske antitrust suits over Google's AI Overviews

Judge Amit P. Mehta granted Google's motions to dismiss two antitrust suits brought by Chegg and Penske Media Corporation on September 30, 2026. The publishers argued that Google forces sites to hand over content for snippets, AI training, and AI Overviews as the price of appearing in search. The court held that the complaints did not plausibly plead an agreement, separate products, antitrust standing, or a defined market. If you run a site that depends on Google traffic, the ruling leaves your options where they were: let Google crawl, or leave its index.

US District Court for the District of Columbiaverified

Connectorsmedium signal

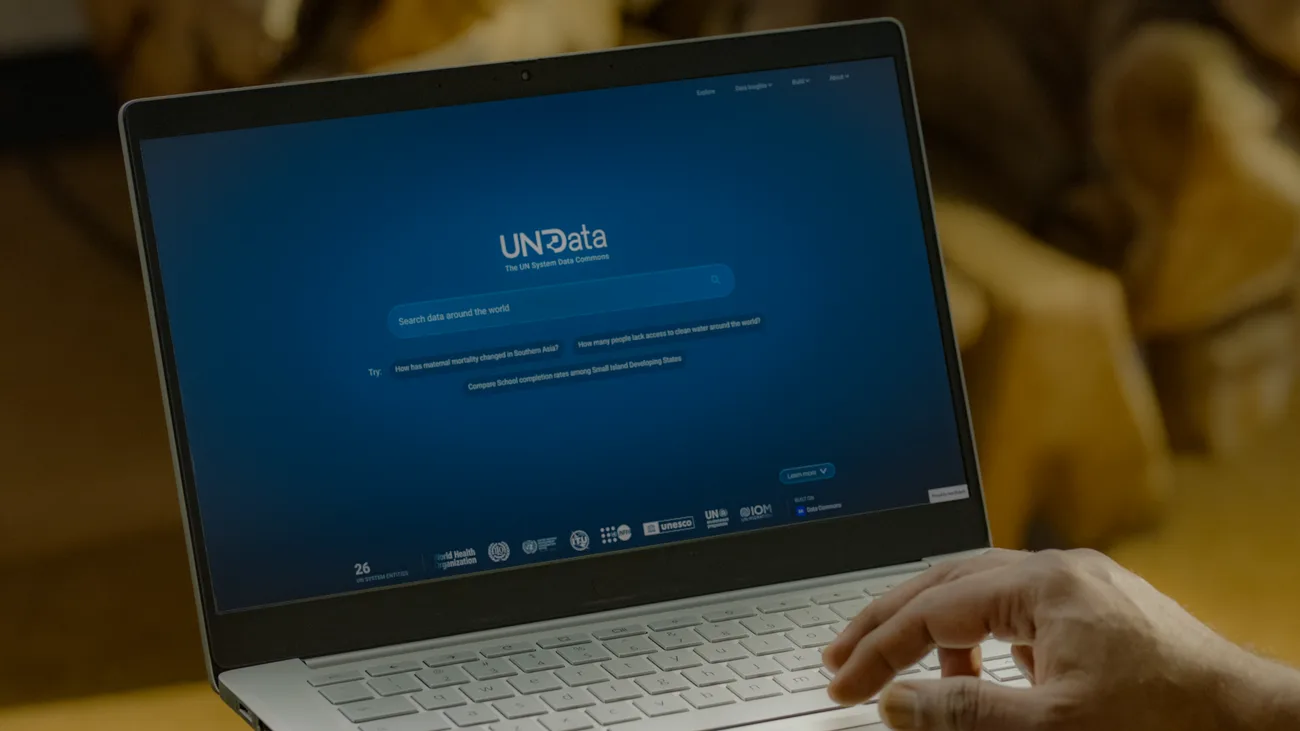
UN statistics now sit behind an MCP connection an agent can query itself

The UN system has opened the UN System Data Commons, a single knowledge graph built from statistics that used to live in separate agency silos. It is searchable in plain language at data.un.org, and it speaks the Model Context Protocol, so an agent can fetch a figure without a person opening a spreadsheet. Google states that every dataset was validated with UN statisticians. The stated goal is 80% of the system's statistical datasets by 2027.

Googleverified

Modelsmedium signal

AWS added model caching to SageMaker HyperPod and measured about 60% faster scale-out

SageMaker HyperPod can now keep model weights on a node's local NVMe and pre-pull the container image, so a pod that used to wait minutes for downloads starts in seconds. AWS reports benchmarks across models from 57 GB to 145 GB showing around 60% faster scale-out, and an image cache that removes over two minutes of pull time, a 97% reduction. Those figures are the vendor's own and arrived without a description of the test. On the same day AWS made TwelveLabs Marengo 3.0 available as an embedding model in Amazon Bedrock Managed Knowledge Base, so a knowledge base can index what a video shows rather than only what was said in it.

AWSverified

Connectorsmedium signal

Amazon Bedrock adds a ServiceNow connector and scheduled syncs to its managed knowledge bases

AWS published three changes to Amazon Bedrock Managed Knowledge Base on September 4, 2026. ServiceNow becomes a native data source, so knowledge articles and service catalog items are crawled without a custom ingestion pipeline. SharePoint, OneDrive, and Confluence can now be connected by signing in with your own credentials instead of waiting for an IT-issued service account. Sync scheduling arrives for every native connector, at daily, weekly, or monthly intervals.

AWSverified

Modelsmedium signal

NeoMME's 260M encoder lands within 0.002 of a 3.75B model on ViDoRe v3

H company published NeoMME on September 3, 2026: a pair of multimodal encoders, at 260M and 800M parameters, released under Apache 2.0 and loadable through Hugging Face Transformers. On the ViDoRe v3 document retrieval benchmark the small one scores 0.523 nDCG@10, which is 0.002 behind ColQwen2.5 at roughly 14 times its parameter count. It also encodes about 51 pages per second on a single NVIDIA L40S, and the index it produces can be compressed from about 1.5 MB per page to 6 kB while keeping more than 95% of retrieval quality.

Hugging Faceverified

Toolsmedium signal

ChatGPT search switched en masse to the site: operator

On August 20, Simon Willison relayed a measurement from Promptwatch showing that ChatGPT abruptly began narrowing its searches to preselected domains. The share of queries carrying the site: operator held between 0.3% and 0.5% for weeks, then jumped to 16% to 17% on August 8 — two days after OpenAI announced accuracy fixes in GPT-5.6. Willison concludes that the search tool internally has the shape search(query, recency, domains), which means the model picks domains before it even frames the question. If you care about visibility in that search, you are no longer competing only for a place in the result but for your domain to make the list the model assembles on its own.

Simon Willisonverified

Industrymedium signal

Google gives sites a button readers use to name them a preferred source

On August 20, Google published a button a publisher places on its own page, which a reader clicks once to add that site to their preferred sources in Search. The consequence is that the site's pages appear more prominently in Top Stories, in AI Overviews, and in AI Mode. Google says users have chosen more than 600,000 different sources so far. Two reader-side changes arrived with it: tuning topics in the Discover feed through a three-dot menu, and a customizable audio briefing in Google News for Android.

Googleverified