Hugging Face measures tokenizers v1 at 3 to 30 times the encode speed of v0.23
Hugging Face published the release candidate of tokenizers v1 on September 21, 2026, together with the numbers behind it. Across the ten model families the new encode path covers, the library encodes 3 to 30 times faster than v0.23 on a single thread of an Apple M4 Max, and it reaches 76% of linear scaling across eight workers. The output does not change: the same text produces the same token IDs, through the same calls. Every figure was measured against the Rust crate, and the Python bindings most of the ecosystem uses add per-call overhead the numbers exclude.
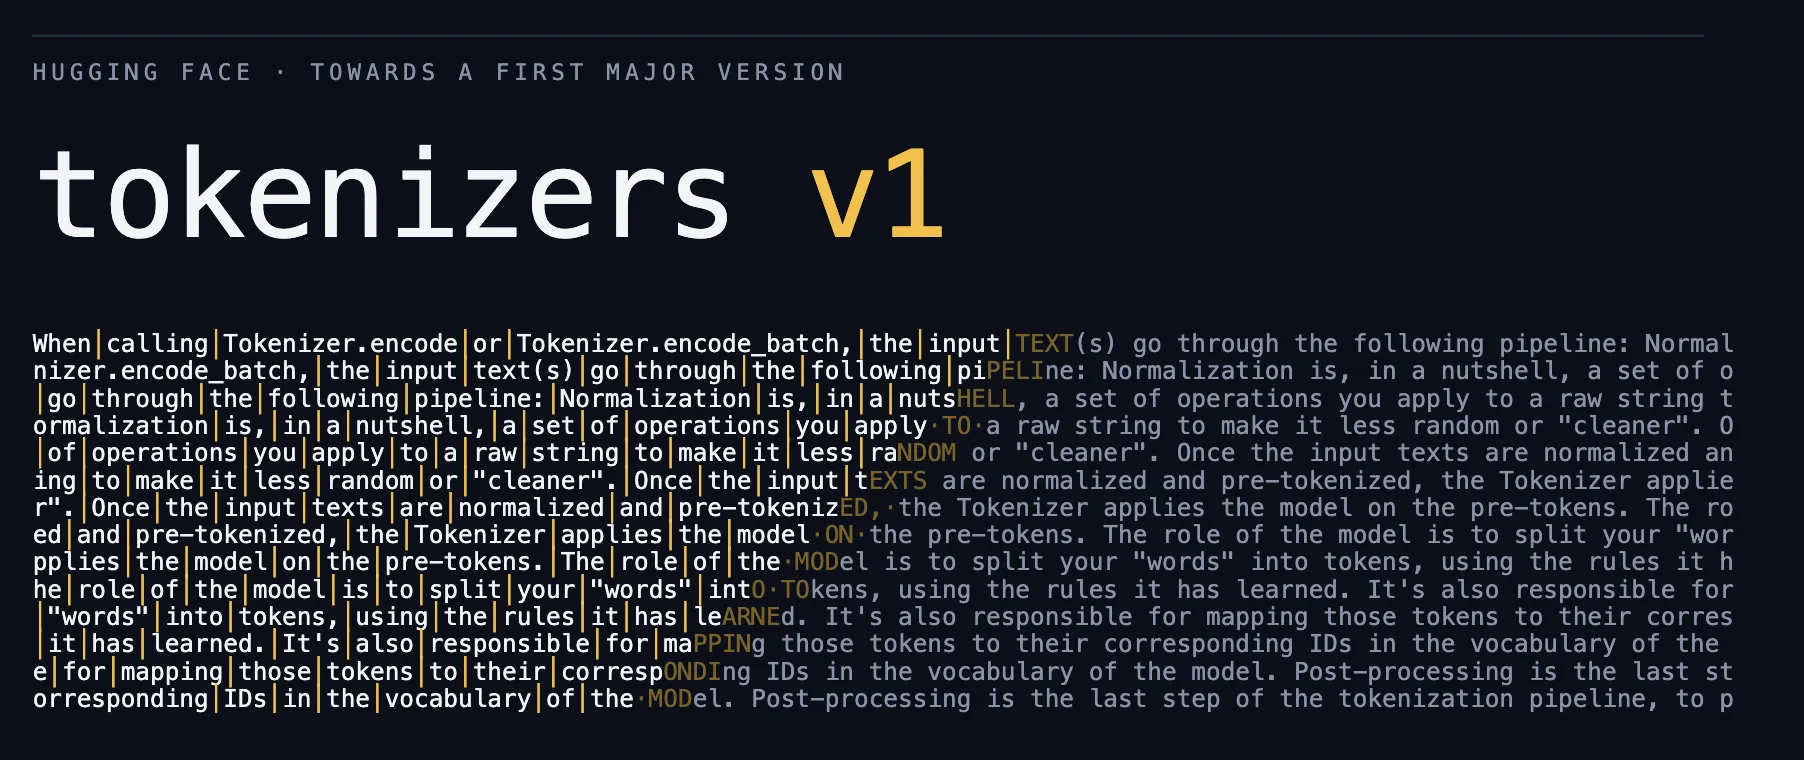
Source
tokenizers v1: encode, decode and scaling, measuredHugging Face Blog · Original published September 21, 2026
The tokenizer is rarely the part of a pipeline anyone profiles. Hugging Face spent the v1 cycle on exactly that part and published the measurements on September 21, 2026. The release candidate encodes 3 to 30 times faster than v0.23 across the ten model families its new encode path covers, on one thread of an Apple M4 Max. What comes out is unchanged: the same text still produces the same token IDs.
What was measured
The headline figure is a range because the gain depends on the tokenizer. The low end, around three times, is t5-base; the high end, around thirty times, is gpt2. Eight of the ten families measured use byte pair encoding, and the other two use WordPiece and Unigram. Across eight workers, encoding reaches 76% of linear scaling, which is the case that matters when one tokenizer serves many concurrent requests.
Small differences in benchmark design produce large differences in tokenizer results, so the method belongs beside the numbers. Every engine runs the same timing loop, vocabulary loading is timed separately and never counted inside encode, and output IDs are hash-verified against the baseline. Workers are pinned to eight distinct physical cores rather than sibling threads, and each repeat starts in a fresh process. The headline numbers come from a stream of distinct documents rather than one document encoded again and again, because that second workload measures a fully warm cache.
- The new encode path covers ten model families, eight of which use byte pair encoding.
- The comparison is against v0.23, on one thread of an Apple M4 Max.
- Multi-threaded encoding reaches 76% of linear scaling across eight physical cores.
- Token IDs, the API, the vocabulary and the merge ranks all stay as they were.
Where the speed comes from
Four changes carry most of the gain, and each one removes work at a different point. Splitting the text no longer runs a general-purpose regex engine. The split pattern ships with the model and never changes at runtime, so v1 replaces the engine with a hand-written function called bitcannon. That function reads the input bytes as parallel bitstreams and decides 64 bytes per register operation using SIMD instructions. A thread-local cache holds the finished IDs of pre-tokens already seen, so a repeated word is merged once. The merge loop keeps its working set in a caller-owned scratch buffer and links symbols by position, and the model is called once per batch of pre-tokens instead of once per pre-token.
The range in the headline number follows from the first of those changes. bitcannon recognizes a handful of split patterns, and the post names GPT-2, cl100k, o200k, Tekken and DeepSeek; a tokenizer whose pattern is not among them stays on the regex path and gets none of the speed-up. One crate was also split into a workspace, so an application links tk-encode and leaves serialization, conversion and training out of the build.
Who gets it today
The release candidate is published as a pre-release crate, and encoding code does not change to use it. The project puts it plainly: "Encoding is unchanged: same call, same ids." Training sits behind a feature that is on by default and pulls in a C++ dependency, so a build that only encodes turns that feature off.
Most of the ecosystem reaches this library through Python, and that is not where the numbers were taken. The bindings wrap the same Rust code but add per-call overhead none of these measurements include, and simpler bindings are listed as 1.0.0 work rather than finished work. This suggests the practical gain arrives in two steps: now for callers in Rust and for services that embed the crate, later for the transformers stack the post names as its next target. Inference-only C and C++ bindings for ExecuTorch and llama.cpp sit on the same 1.0.0 list.
„Encoding is unchanged: same call, same ids.“
Related
Python 3.15 makes UTF-8 the default encoding and adds explicit lazy imports
Python 3.15.0 came out on October 9, 2026. Files opened without an explicit encoding are now read and written as UTF-8 on every system, and a new lazy import statement defers loading a module until it is used. The release also adds frozendict and a sampling profiler.
Python Software Foundationverified
Deno's team joins Cloudflare, and the Deno runtime gets one more year of updates
Ryan Dahl announced on October 9, 2026 that the whole Deno team is moving to Cloudflare. The Deno runtime will get monthly fixes for one more year before development ends, and Deno Deploy will shut down after six months. JSR keeps running.
Denoverified
Anthropic's OSS Scanner sends open-source maintainers free vulnerability reports that no human has reviewed
Anthropic launched OSS Scanner on October 8, 2026, an opt-in service that scans eligible open-source projects with its strongest models, including Claude Mythos, at no cost. Each report includes a reproducer, an explanation, and a candidate patch when one exists, but no person checks it before it is sent. Anthropic says it expects more than 90% of findings to be real.
Anthropicverified