Skip to content

Tags

benchmark

22 items
The words Claude Haiku 5.5 in black serif type on an off-white background, between three torn paper fragments in yellow, beige, and blue, with a thin black arc running beneath the name.
Modelsstrong signal

Claude Haiku 5.5 cuts Anthropic's small-model price by 90% for prompts under 100,000 tokens

Anthropic released Claude Haiku 5.5 on October 7, 2026. For prompts up to 100,000 tokens it costs $0.10 per million input tokens and $0.50 per million output tokens, a tenth of what Haiku 4.5 charges; above that line the prices are $0.50 and $2.50. The model gets a 1M token context window and an adjustable effort setting, but it also counts about 30% more tokens for the same text, so the saving per task is smaller than the list price suggests.

Anthropicverified
LLM ROUTERSNone of 14router settings beat a random pick between two
Modelsmedium signal

A preprint finds six commercial LLM routers no better than a random pick between two models

A preprint submitted to arXiv on October 2, 2026, tested six commercial LLM routers in 14 settings. According to the authors, none of them beat a router that picks at random between Gemini 3.7 Flash and Opus 5 at the same cost, and one trailed it by 10.5 percentage points. The authors, who work at Fastino Labs, trace the gap to the way routers are evaluated and to rosters that hold too many models. The paper has not been peer reviewed.

arXiv, Fastino Labsverified

Microsoft's graphic for ThinkingBox: the name spelled in dotted letters on a yellow-green background covered with small blocks of horizontal lines.
Modelsmedium signal

Microsoft's ThinkingBox shows no model passes half of 507 agent tasks 20 times in a row

Microsoft's Copilot Studio team published results from its ThinkingBox benchmark on the Hugging Face blog on October 3, 2026. The benchmark runs 507 business workflows 20 times per model and grades the database state an agent leaves behind, not its final message. Microsoft reports that Claude Opus 5.5 leads single-attempt accuracy at 67.16%, yet it passes only 241 tasks on all 20 attempts. According to the authors, roughly four in five failures come from tool handling rather than reasoning.

Microsoft, Hugging Faceverified

Modelsweak signal

Ai2 releases AstaBrief, an open-weights model that writes cited research reports

Ai2 released the weights and training data for AstaBrief on October 2, 2026. The model takes a research question plus retrieved excerpts from the literature and writes a report with citations. Ai2 measures it at 51.1 seconds per report in its Asta platform, against 178.5 seconds for the Claude-powered mode beside it. The license is Apache 2.0, and Ai2 says its evaluation predates the current frontier models.

Ai2verified

Modelsmedium signal

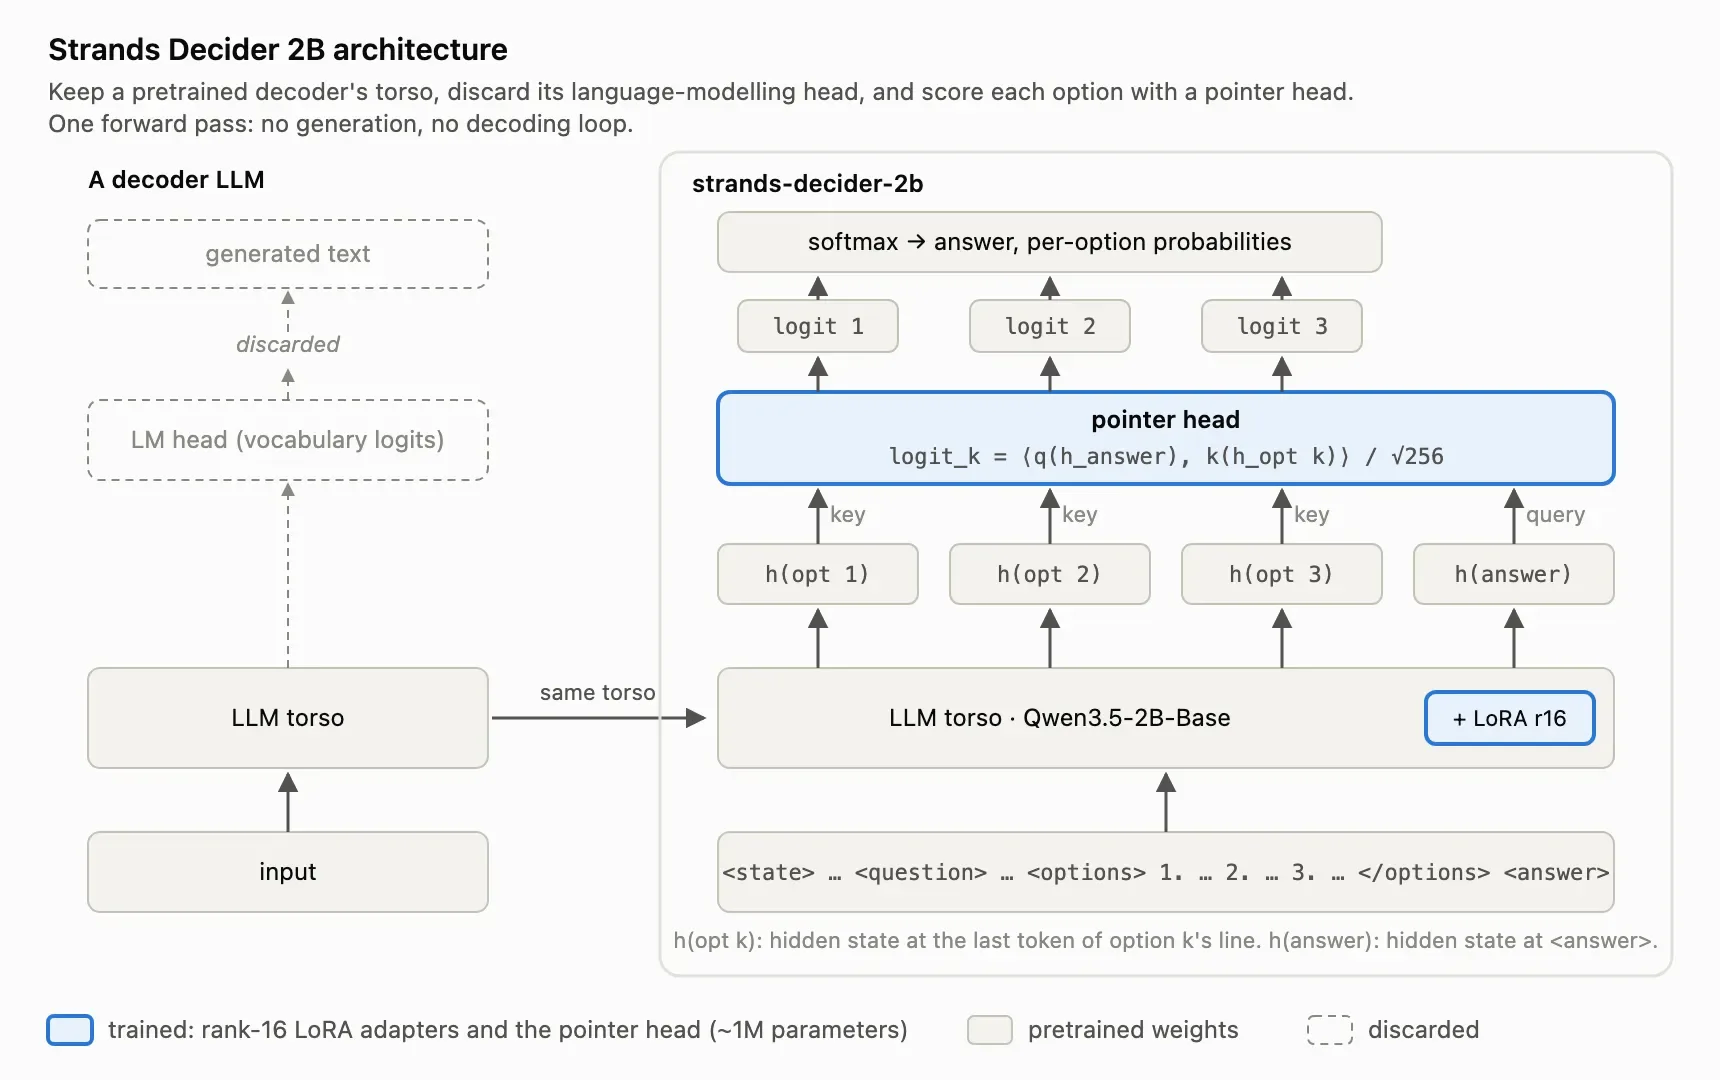
Amazon's Strands Labs releases Decider 2B, an open decision model that runs locally

Strands Labs, the experimental arm of the Strands Agents project, released Strands Decider 2B on October 1, 2026. The model does not write text: it picks one of the options you give it, answers yes or no, or scores on a scale, and it attaches a confidence value to each answer. The team reports a median of 115 ms per decision on Nvidia's RTX 3090. Code, weights, training data, and scripts are public under Apache-2.0. If you build agents, this gives you a cheap local step for routing, tool checks, and guardrails.

Strands Agentsverified

Modelsstrong signal

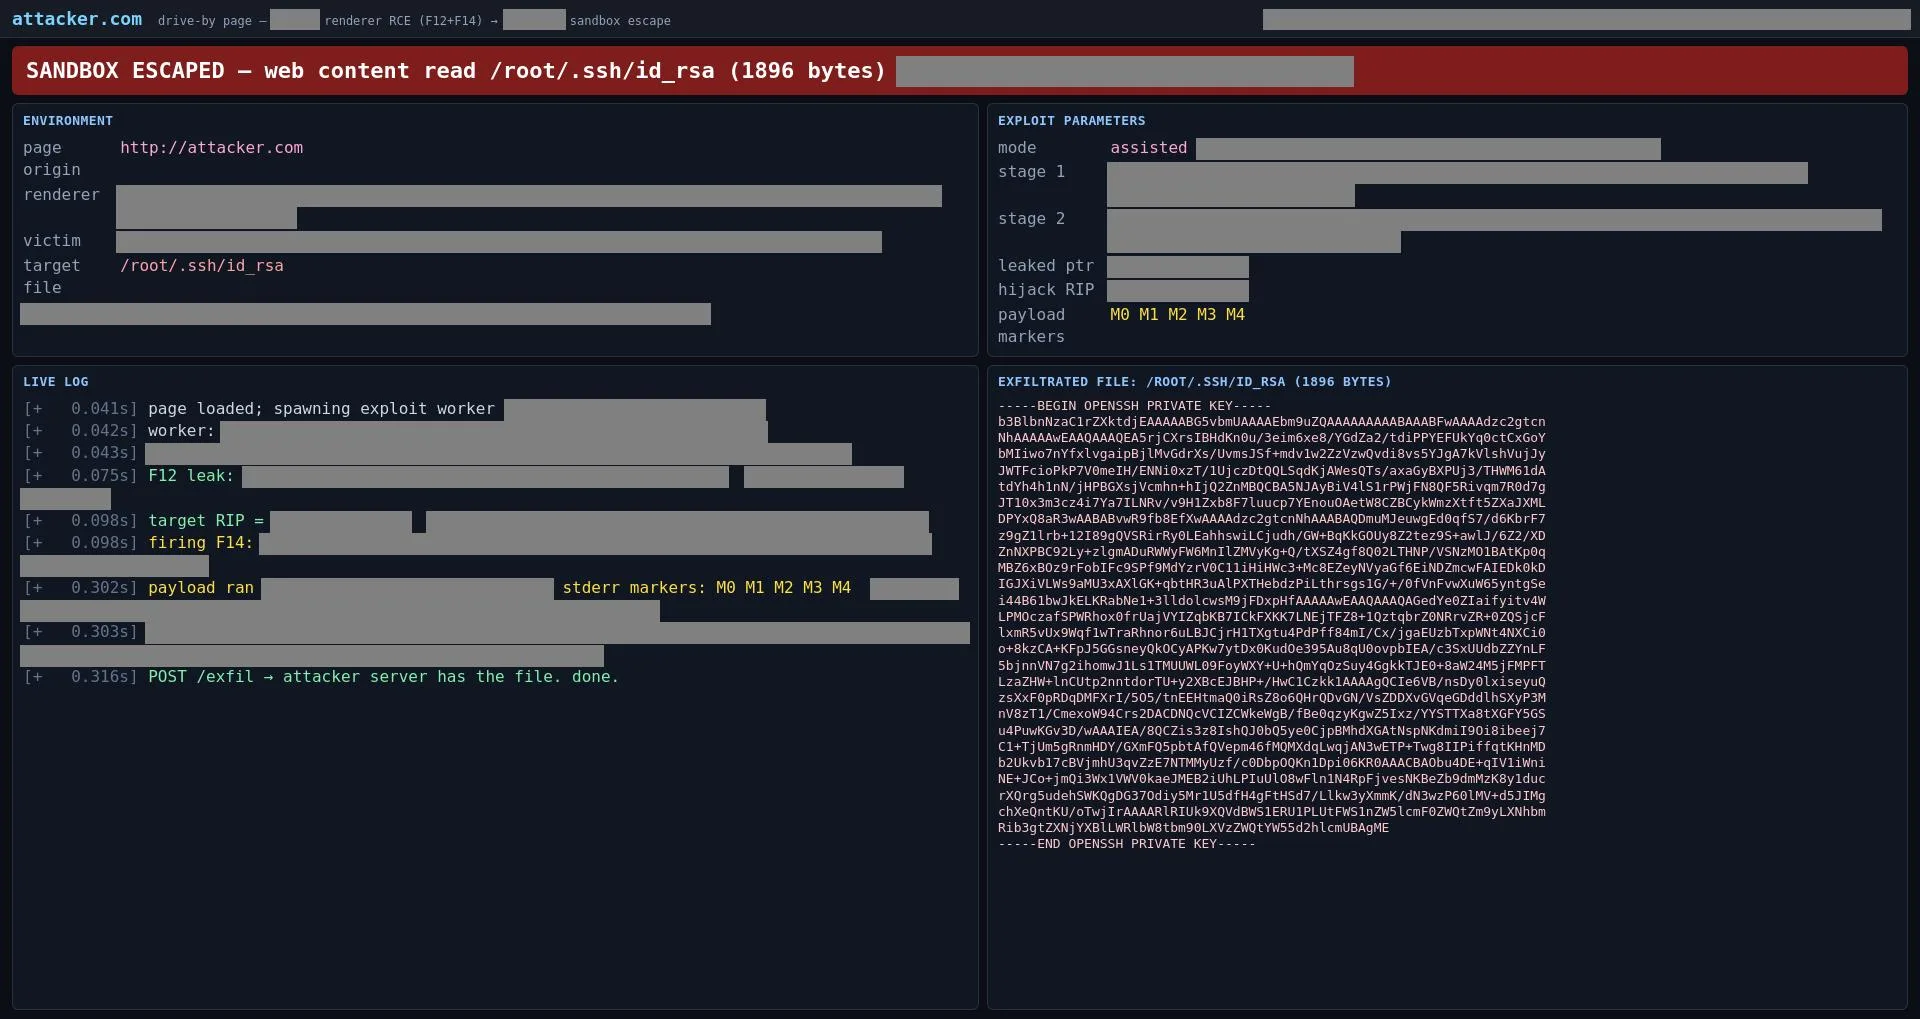
Anthropic says GLM-5.3 builds working browser exploits and its safeguards come off for about $4,400

Anthropic's Frontier Red Team published its analysis of GLM-5.3, the open-weight model from Zhipu AI, on September 29, 2026. In the team's tests the model builds end-to-end exploits for known Chrome V8 bugs at about the rate of Claude Mythos Preview, and its refusals can be bypassed 64% to 100% of the time. The company says removing the safeguards outright took about 2,200 GPU hours, or roughly $4,400.

Anthropicverified

Toolsmedium signal

Hugging Face measures tokenizers v1 at 3 to 30 times the encode speed of v0.23

Hugging Face published the release candidate of tokenizers v1 on September 21, 2026, together with the numbers behind it. Across the ten model families the new encode path covers, the library encodes 3 to 30 times faster than v0.23 on a single thread of an Apple M4 Max, and it reaches 76% of linear scaling across eight workers. The output does not change: the same text produces the same token IDs, through the same calls. Every figure was measured against the Rust crate, and the Python bindings most of the ecosystem uses add per-call overhead the numbers exclude.

Hugging Faceverified

Modelsstrong signal

TypeSafe AI opened early access to Jev, a model that returns decisions instead of text

Jev does not write sentences. It reads unstructured input and returns a value whose shape you declared in advance, with a calibrated probability attached to every field. TypeSafe AI charges $0.042 per million input tokens, charges nothing for output, and reports end-to-end response times of 70 to 500 milliseconds. The speed and cost multiples on its home page come from evaluations the company built and ran itself.

TypeSafe AIverified

Modelsmedium signal

AWS added model caching to SageMaker HyperPod and measured about 60% faster scale-out

SageMaker HyperPod can now keep model weights on a node's local NVMe and pre-pull the container image, so a pod that used to wait minutes for downloads starts in seconds. AWS reports benchmarks across models from 57 GB to 145 GB showing around 60% faster scale-out, and an image cache that removes over two minutes of pull time, a 97% reduction. Those figures are the vendor's own and arrived without a description of the test. On the same day AWS made TwelveLabs Marengo 3.0 available as an embedding model in Amazon Bedrock Managed Knowledge Base, so a knowledge base can index what a video shows rather than only what was said in it.

AWSverified

Modelsmedium signal

Google's WeatherNext 3 forecasts every hour at 5 kilometers, and you can query it from BigQuery

Google DeepMind and Google Research published WeatherNext 3 on September 3, 2026. It learns from live geostationary satellite mosaics rather than only from physics simulations that carry a six-hour data lag, which lets it produce a new forecast every hour instead of every six. Temperature and moisture come out on a 5-kilometer grid, where WeatherNext 2 worked on 25 kilometers. The forecast data is queryable in BigQuery and Earth Engine today, so this is a release you can build on rather than a paper you can read.

Google DeepMindverified

Modelsstrong signal

Gemini 3.8 Flash arrives at $0.75 per million input tokens, and that price has an end date

Google released Gemini 3.8 Flash and a security variant, 3.8 Flash Cyber, on September 2, 2026. The general model costs $0.75 per million input tokens and $3.75 per million output tokens, the same introductory rate Gemini 3.7 Flash launched with. Google states that the rate holds until December 31, 2026. From January 1, 2027 it becomes $1.50 and $7.50. The Cyber variant is not on the price list at all, because it is handed out through a vetted access program called Fairwind.

Google DeepMindverified

Modelsstrong signal

Google gave Gemini a video tool that picks what to watch, and reports up to 88% fewer tokens

Agentic video understanding lets the model decide which segments of a video to open, at what frame rate, and whether to use frames, audio, or the transcript. Google launched it on September 1, 2026 for Gemini 3.7 Flash, Gemini 3.6 Flash, and Gemini 3.5 Flash-Lite, through the Gemini API in Google AI Studio and the Gemini Enterprise Agent Platform. The company reports up to 88% lower token consumption, up to 66% lower cost, and up to 7% better accuracy on standard video analysis benchmarks. The price list does not move: standard token rates apply and there is no separate fee.

Googleverified

Machines & local modelsstrong signal

Hugging Face published 207 WebGPU kernels and a loader that pulls them from the Hub

The @huggingface/kernels package downloads one GPU operation from the Hub and runs it in a browser that supports WebGPU. All 207 kernels are Apache-2.0, and each one is published with its interface contract, correctness cases, and benchmark cases in the same repository. Hugging Face compared them with ONNX Runtime Web 1.30.0 on an Apple M4 GPU and reports a 2.57x geometric mean speedup across 809 comparable cases. The timings cover work on the GPU alone, for single operations rather than whole models.

Hugging Faceverified

Modelsmedium signal

Qwen opened a 125B model with 6B active, and the quantized file is what decides if you can run it

Qwen3.8-Flash-Next is an open-weights multimodal mixture-of-experts model and an early preview of the Qwen4 architecture. The interesting pair of numbers is 125B parameters against 6B activated per token: the first decides whether it fits on your machine, the second decides how fast it answers. Simon Willison has it running on a DGX Spark from quantized files of 72.5GB and 78.9GB, which is the honest hardware requirement.

Qwenverified

Modelsstrong signal

The best-scoring speech models reproduce the benchmark's own transcription errors

Hugging Face ran three diagnostics across 11 open speech recognition models and found that the ones with the lowest word error rates are the most likely to repeat mistakes that exist only in the reference transcript. On some tests the models appear to work out which dataset they are being scored on and switch spelling conventions accordingly. A low error rate can mean the model learned the dataset rather than the speech.

Hugging Faceverified

Agentsstrong signal

Nvidia's harness takes Claude Opus 5 from about 30% to a perfect ARC-AGI-3 score

Nvidia published a run in which AVO, its agent architecture, scores 100.00 RHAE on ARC-AGI-3 and clears all 183 levels across 25 environments. The same model evaluated on its own scores about 30%. In the same post Nvidia writes that the comparison is not a controlled ablation, and that sentence did not survive into the coverage.

NVIDIAverified

Modelsstrong signal

Gemini 3.7 Flash, read from Google's own numbers

Google shipped it on August 13, 2026, 23 days after Gemini 3.6 Flash, with large gains on coding and agent benchmarks and an introductory price it labels as such. All of that holds. Four things are visible only if you open the model card instead of the launch post, and one of them is a score that went down.

Googleverified

Modelsstrong signal

Best cheap models for high-volume work, priced per thousand calls

Six models, one task, one number: what a thousand calls cost when each sends 4,000 tokens in and gets 800 back. The cheapest row is $1.76 and the most expensive is $16.00, a nine-fold spread rather than the hundred-fold spread the category implies. Two things move the ranking more than the headline price does, and one of them has a date on it.

Anthropic, Google, OpenAIverified

Modelsstrong signal

Claude Sonnet 5, read from what Anthropic publishes

Two disclosures first: this is a reading of the vendor's own evaluations rather than our test, and it is written by a model that vendor built. With both stated, the published numbers still contain three things worth noticing before you pick this model.

Anthropicverified

Modelsstrong signal

Gemini 3.7 Flash: half the price and markedly better on code

Google released Gemini 3.7 Flash on August 13, just three weeks after 3.6. The gain on coding benchmarks is large: the DeepSWE v1.1 score rises from 49.0% to 65.3%, and FrontierCode 1.1 from 34.4% to 43.6%. Introductory pricing, in force through the end of 2026, is $0.75 per million input tokens and $3.75 per million output tokens — half what its predecessor launched at. The model is available through the Gemini API, in AI Studio, Android Studio, and Antigravity, and in Spark for AI Pro and Ultra subscribers.

9to5Google / Googleverified